2 Reference
Every binding below is provided by glmnet, except those of Nested lists and vectors, CSV files, Matrices from math/matrix, Polars dataframes, Example datasets and Plots, whose sections name the modules that provide them. Each model family has a fit procedure, a path fitter, a cross-validation procedure, a transparent result struct and prediction helpers. The formula front end (Formulas) fits any family from a table. Every result type, glmnet-path, glmnet-cv and formula-model also implement the generic interface of Generic model interface: predict, coef and deviance-ratio work on all of them, and they print as summaries. Concepts explains how the pieces fit together.
2.1 Common arguments
The fit procedures share their argument conventions:
X is a design matrix, one row per observation: a design-matrix? value, a non-empty list or vector of equal-length rows of reals, each row a list or a vector (see design-matrix/c, Input data and Nested lists and vectors), or a math/matrix matrix. Prediction helpers take new data in the same forms, with as many columns as the fit has coefficients.
A response y, and an unnamed Cox fit’s statuses, is a non-empty list, vector, flvector or f64vector with one entry per row of X (see response/c), a math/array array or a Polars series; a Cox status may also be a boolean, #t for an event.
Every procedure also takes named data, a table or a Polars dataframe, whose response and predictors it selects by name (see Data arguments).
#:lambda is the penalty strength λ ≥ 0. It is required.
#:alpha is the mixing parameter α ∈ [0, 1]: 0.0 is the ridge penalty, 1.0 (the default) the lasso, and values in between the elastic net.
#:standardize? scales each predictor to unit variance before fitting; coefficients are always reported on the original scale.
#:intercept? fits an unpenalized intercept; #f fixes it at zero.
#:thresh is the coordinate-descent convergence threshold and #:max-iters the maximum number of passes.
Before the solver runs, an argument of the wrong type, a ragged or empty matrix, a non-finite entry, or a response of the wrong length raises exn:fail:contract; the message names the offending row and column or position. A fatal condition reported by glmnet raises exn:fail with a readable message. So does a fit for which glmnet fits no λ at all, for example because it does not converge within #:max-iters passes; the message names the procedure called and gives glmnet’s reason. (R warns instead, and returns an empty model.)
2.1.1 Data arguments
The fit, path and cross-validation procedures take their data as it is, and give the results of the explicit conversions of Input data, Matrices from math/matrix and Polars dataframes. Unnamed data is as above. Named data, a table that is not a design matrix or a Polars dataframe, is read by column name: y names the response, and #:predictors, then required, lists the predictor columns in the order of the coefficients. Nothing is guessed: a column is used only when it is named, no row is dropped, and a missing value, a value that is not a real number or one that is not finite is an error naming its column and row. A design matrix is unnamed data, even when its columns have names. An association list whose columns are lists, such as '(("x" 1 2) ("y" 3 4)), is also a list of rows: it is named data when y names columns, and rows otherwise. A list of strings or symbols given to a binomial or multinomial fitter is class labels, never column names.
The response is one column, except for two families:
Family |
| y for named data |
| Unnamed data |
Gaussian, Poisson |
| a numeric column |
| a response |
Binomial, multinomial |
| a column of class labels |
| a response of class labels |
Cox |
| '("time" "status"), two columns |
| the times, and the statuses after them |
Multi-response |
| '("y1" "y2"), a non-empty list |
| a matrix, one column per response |
A binomial or multinomial response, a column, a list, a vector, a Polars series or a math/array array, may hold strings, symbols or booleans in place of class numbers. Its classes are then its levels, as a formula’s factor response has them: strings and symbols sorted by string<?, which is R’s order in the C locale (R in another locale sorts mixed-case labels differently), and "FALSE" before "TRUE". A binomial response has exactly two. The fit remembers them, and predict with #:type 'class, logistic-predict and multinomial-predict return them.
A fit from named data remembers its predictors’ names: predict and the prediction helpers read new named data, and a design matrix with column names, by them, in any order, ignoring other columns, the response included, and other unnamed data by position. A fit from unnamed data reads only unnamed data. The result is the same struct as from the explicit conversions, and equal? to it, though a copy made by struct-copy does not remember the names; coef keeps its layout, and plot-coefficient-path labels the curves by name and a multi-response fit’s panels by its responses’ names.
(require glmnet) loads neither Polars nor math/matrix; their values are recognised once the program has loaded the library itself.
> (define autos (dataframe (list (series '(21.0 22.8 21.4 18.7 18.1 14.3) #:name "mpg") (series '(2.62 2.32 3.215 3.44 3.46 3.57) #:name "wt") (series '(110 93 110 175 105 245) #:name "hp")))) > (define car-fit (ols autos "mpg" #:predictors '("wt" "hp"))) > (coef car-fit) '#(31.51526192771049 -2.5190175381213304 -0.030876933077271105)
> (predict car-fit (hash "hp" '(150) "wt" '(3.0) "model" '("new"))) '(19.326669351755836)
> (predict car-fit '((3.0 150))) '(19.326669351755836)
> (equal? (ols (matrix [[2.62 110] [2.32 93] [3.215 110] [3.44 175] [3.46 105] [3.57 245]]) (array #[21.0 22.8 21.4 18.7 18.1 14.3])) (ols '((2.62 110) (2.32 93) (3.215 110) (3.44 175) (3.46 105) (3.57 245)) '(21.0 22.8 21.4 18.7 18.1 14.3))) #t
> (define flowers (multinomial-fit iris "Species" #:lambda 0.05 #:predictors '("Petal.Length" "Petal.Width"))) > (multinomial-predict flowers (hash "Petal.Length" '(1.4 4.5 6.0) "Petal.Width" '(0.2 1.5 2.5))) '("setosa" "versicolor" "virginica")
> (ols autos "mpg") ols: contract violation
#:predictors is required when X is a dataframe; it names
the predictor columns, as in #:predictors '("wt" "hp")
in: (->*
(data/c (response-for/c X real?))
(#:predictors (predictors-for/c X y) ...)
elnet-result?)
contract from: <pkgs>/glmnet/core/elnet.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/elnet.rkt:37:3
> (ols autos "mpg" #:predictors '("wt" "mpg")) ols: contract violation
expected: a non-empty list of distinct names of numeric
columns of the dataframe, without the response
given: column "mpg", which is the response
in: the #:predictors argument of
(->*
(data/c (response-for/c X real?))
(#:predictors (predictors-for/c X y) ...)
elnet-result?)
contract from: <pkgs>/glmnet/core/elnet.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/elnet.rkt:37:3
value
> (contract-first-order-passes? data/c '((1.0 2.0) (3.0 4.0))) #t
> (contract-first-order-passes? data/c autos) #t
> (contract-first-order-passes? data/c (hash "x" '(1 2))) #t
> (contract-first-order-passes? data/c '(1.0 2.0)) #f
procedure
(named-data? v) → boolean?
v : any/c
> (named-data? autos) #t
> (named-data? (list (cons "x" '(1 2)))) #t
> (named-data? (rows->design-matrix '((1 2)) #:column-names '(a b))) #f
procedure
(response-for/c X elem [#:classes? classes?]) → flat-contract?
X : data/c elem : flat-contract? classes? : boolean? = #f
> (contract-first-order-passes? (response-for/c autos real?) "mpg") #t
> (contract-first-order-passes? (response-for/c autos real?) "weight") #f
> (contract-first-order-passes? (response-for/c '((1.0) (2.0)) real?) '(3 4)) #t
> (contract-first-order-passes? (response-for/c '((1.0) (2.0)) (or/c 0 1) #:classes? #t) '(yes no)) #t
procedure
(survival-for/c X) → flat-contract?
X : data/c
> (define survival (list (cons "x" '(1 2 3)) (cons "t" '(5.0 3.0 6.0)) (cons "d" '(1 0 1)))) > (contract-first-order-passes? (survival-for/c survival) '("t" "d")) #t
> (contract-first-order-passes? (survival-for/c survival) "t") #f
procedure
(statuses-for/c X y) → flat-contract?
X : data/c y : any/c
> (contract-first-order-passes? (statuses-for/c '((1.0) (2.0)) '(5.0 3.0)) '(1 0)) #t
> (contract-first-order-passes? (statuses-for/c '((1.0) (2.0)) '(5.0 3.0)) '(#t #f)) #t
> (contract-first-order-passes? (statuses-for/c survival '("t" "d")) '(1 0 1)) #f
procedure
X : data/c
> (contract-first-order-passes? (responses-for/c autos) '("mpg" "hp")) #t
> (contract-first-order-passes? (responses-for/c '((1.0) (2.0))) '((3.0 4.0) (5.0 6.0))) #t
procedure
(predictors-for/c X y [#:classes? classes?]) → flat-contract?
X : data/c y : any/c classes? : boolean? = #f
> (define car-predictors/c (predictors-for/c autos "mpg")) > (contract-first-order-passes? car-predictors/c '("wt" hp)) #t
> (contract-first-order-passes? car-predictors/c '("wt" "mpg")) #f
> (contract-first-order-passes? car-predictors/c '("wt" "wt")) #f
> (contract-first-order-passes? (predictors-for/c '(("x" 1 2) ("d" 1 0)) '("d") #:classes? #t) '("x")) #f
2.2 Input data
| (require glmnet/data) | package: glmnet |
A design-matrix? value holds a design matrix in the layout the Fortran reads: an array of doubles stored column by column, so that element (i, j) of a matrix with n rows is at index i + jn, with indices counted from 0. It also records the numbers of rows and columns, and optional column names. See Data.
Every conversion into a design matrix copies its input and checks it: the matrix needs at least one row and one column, every row (or column) the same length, and every entry must be a real, finite number. Exact numbers become flonums. A violation raises exn:fail:contract, with a message that names the offending row and column. Because nothing can modify a design matrix after it is built, it passes these checks for its whole life, and one design matrix can be passed to any number of fits.
glmnet re-exports every binding in this section. glmnet/data provides them without loading the native library.
procedure
(design-matrix? v) → boolean?
v : any/c
> (define D (rows->design-matrix '((1.0 4.0) (2.0 5.0) (3.0 6.0)))) > (design-matrix? D) #t
> D #<design-matrix 3x2>
> (equal? D (columns->design-matrix '((1 2 3) (4 5 6)))) #t
value
> (contract-first-order-passes? design-matrix/c D) #t
> (contract-first-order-passes? design-matrix/c '((1.0 2.0) (3.0 4.0))) #t
> (contract-first-order-passes? design-matrix/c (vector #(1.0 2.0) '(3.0 4.0))) #t
> (contract-first-order-passes? design-matrix/c '(1.0 2.0)) #f
procedure
(response/c elem) → flat-contract?
elem : flat-contract?
> (require racket/flonum) > (define labels/c (response/c (or/c 0 1))) > (contract-first-order-passes? labels/c '(0 1 1)) #t
> (contract-first-order-passes? labels/c (flvector 0.0 1.0)) #t
> (contract-first-order-passes? labels/c (vector 0 2)) #f
> (contract-first-order-passes? labels/c (vector)) #f
> (define/contract (events statuses) (-> (response/c (or/c 0 1)) exact-nonnegative-integer?) (for/sum ([s statuses]) (if (= s 1) 1 0))) > (events (vector 1 0 1)) 2
> (events (flvector 1.0 0.0 0.5)) events: contract violation
expected: (or/c 0 1)
given: 0.5
in: the element at position 2 of
the 1st argument of
(-> (response/c (or/c 0 1)) natural?)
contract from: (function events)
blaming: program
(assuming the contract is correct)
at: eval:50:0
> (contract-equivalent? (response/c (>/c 0)) (response/c (>/c 0))) #t
procedure
(rows->design-matrix rows [ #:column-names column-names]) → design-matrix? rows : (listof list?) column-names : (or/c #f (listof (or/c string? symbol?))) = #f
> (define named (rows->design-matrix '((1 2) (3 4)) #:column-names '(age dose))) > (design-matrix->rows named) '((1.0 2.0) (3.0 4.0))
> (design-matrix-column-names named) '("age" "dose")
> (rows->design-matrix '((1.0 2.0) (3.0 4.0) (5.0))) rows->design-matrix: the matrix has rows of different
lengths
row: 2
length: 1
length of row 0: 2
> (rows->design-matrix '((1.0 2.0) (3.0 +inf.0))) rows->design-matrix: the matrix has an element that is not
finite
column: 1
row: 1
element: +inf.0
> (rows->design-matrix '((1.0 2.0)) #:column-names '(a)) rows->design-matrix: the number of column names does not
match the columns
column names: 1
columns: 2
> (rows->design-matrix '((1.0 2.0)) #:column-names '("x" x)) rows->design-matrix: the column names are not distinct
duplicate: 'x
column names: '("x" x)
procedure
(columns->design-matrix columns [ #:column-names column-names]) → design-matrix? columns : (listof list?) column-names : (or/c #f (listof (or/c string? symbol?))) = #f
> (design-matrix->rows (columns->design-matrix '((1 2 3) (4 5 6)))) '((1.0 4.0) (2.0 5.0) (3.0 6.0))
> (columns->design-matrix '((1.0 2.0 3.0) (4.0 +nan.0 6.0))) columns->design-matrix: the matrix has an element that is
not finite
column: 1
row: 1
element: +nan.0
procedure
(f64vector->design-matrix v nrows ncols [ #:column-names column-names]) → design-matrix? v : f64vector? nrows : exact-positive-integer? ncols : exact-positive-integer? column-names : (or/c #f (listof (or/c string? symbol?))) = #f
> (require ffi/vector) > (define v (f64vector 1.0 2.0 3.0 4.0 5.0 6.0)) > (design-matrix->rows (f64vector->design-matrix v 3 2)) '((1.0 4.0) (2.0 5.0) (3.0 6.0))
> (design-matrix->rows (f64vector->design-matrix v 2 3)) '((1.0 3.0 5.0) (2.0 4.0 6.0))
> (f64vector->design-matrix v 4 2) f64vector->design-matrix: contract violation
expected: an f64vector of length nrows * ncols = 8
given: an f64vector of length 6
in: the v argument of
(->i
((v
(nrows ncols)
(f64vector-length/c nrows ncols))
(nrows exact-positive-integer?)
(ncols exact-positive-integer?))
(#:column-names
(column-names
(or/c
#f
(listof (or/c string? symbol?)))))
(result design-matrix?))
contract from: <pkgs>/glmnet/data.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/data.rkt:34:3
procedure
dm : design-matrix?
procedure
dm : design-matrix?
> (design-matrix-nrows D) 3
> (design-matrix-ncols D) 2
procedure
(design-matrix-column-names dm) → (or/c #f (listof string?))
dm : design-matrix?
> (design-matrix-column-names D) #f
> (define cols '((1 2) (3 4)))
> (design-matrix-column-names (columns->design-matrix cols #:column-names '("x1" x2))) '("x1" "x2")
procedure
(design-matrix-ref dm i j) → flonum?
dm : design-matrix? i : exact-nonnegative-integer? j : exact-nonnegative-integer?
> (design-matrix-ref D 2 1) 6.0
> (design-matrix-ref D 3 0) design-matrix-ref: contract violation
expected: (integer-in 0 2)
given: 3
in: the i argument of
(->i
((dm design-matrix?)
(i
(dm)
(integer-in
0
(sub1 (design-matrix-nrows dm))))
(j
(dm)
(integer-in
0
(sub1 (design-matrix-ncols dm)))))
(result flonum?))
contract from: <pkgs>/glmnet/data.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/data.rkt:43:3
procedure
(design-matrix-select-rows dm rows) → design-matrix?
dm : design-matrix? rows : (and/c (listof exact-nonnegative-integer?) pair?)
> (design-matrix->rows (design-matrix-select-rows D '(2 0))) '((3.0 6.0) (1.0 4.0))
> (design-matrix->rows (design-matrix-select-rows D '(1 1))) '((2.0 5.0) (2.0 5.0))
> (design-matrix-select-rows D '(0 3)) design-matrix-select-rows: row index is out of range
row index: 3
valid range: [0, 2]
design matrix: #<design-matrix 3x2>
procedure
(design-matrix->rows dm) → (listof (listof flonum?))
dm : design-matrix?
procedure
(design-matrix->columns dm) → (listof (listof flonum?))
dm : design-matrix?
> (design-matrix->rows D) '((1.0 4.0) (2.0 5.0) (3.0 6.0))
> (design-matrix->columns D) '((1.0 2.0 3.0) (4.0 5.0 6.0))
procedure
dm : design-matrix?
> (f64vector->list (design-matrix->f64vector D)) '(1.0 2.0 3.0 4.0 5.0 6.0)
procedure
y : (or/c list? vector? flvector? f64vector?)
> (f64vector->list (response->f64vector '(1 1/2 2.5))) '(1.0 0.5 2.5)
> (f64vector->list (response->f64vector (vector 1 1/2 2.5))) '(1.0 0.5 2.5)
> (f64vector->list (response->f64vector (flvector 1.0 0.5 2.5))) '(1.0 0.5 2.5)
> (response->f64vector (flvector 1.0 +nan.0 2.0)) response->f64vector: the response has an element that is not
finite
position: 1
element: +nan.0
2.2.1 Tables
A table holds named columns, and is what the formula front end (Formulas) fits from. A column name is a string or a symbol, and names are compared as strings; a column is a list, vector, flvector or f64vector of reals, or a list or vector of strings, symbols or booleans, which the formula front end reads as a factor. A table is one of:
a non-empty association list of (name . column) pairs, whose columns are in the list’s order;
a non-empty hash from name to column, whose columns are in the order of their names, sorted with string<?;
a design-matrix? with column names, in the order of its columns.
Only the columns that are selected are checked: every entry of a column selected as numbers must be a real, finite number, and the selected columns must have the same length, at least 1. An error names the column, and the row of an entry that is wrong. The guide’s Formulas and named data chapter shows tables in use.
> (define patients (list (cons "age" '(34 51 67)) (cons 'dose #(2.0 5.5 1.0)) (cons "id" '("a" "b" "c")))) > (table? patients) #t
> (table? (hash "x" '(1 2))) #t
> (table? named) #t
> (table? D) #f
> (table? '((1 2) (3 4))) #f
procedure
(table-column-names table) → (listof string?)
table : table?
> (table-column-names patients) '("age" "dose" "id")
> (table-column-names (hash 'b '(1) "a" '(2))) '("a" "b")
> (table-column-names (hash "a" '(1) 'a '(2))) table-column-names: the table has two columns with the same
name
name: "a"
procedure
(table->design-matrix table [names]) → design-matrix?
table : table?
names : (and/c (listof (or/c string? symbol?)) pair?) = (table-column-names table)
> (define P (table->design-matrix patients '(dose "age"))) > (design-matrix->rows P) '((2.0 34.0) (5.5 51.0) (1.0 67.0))
> (design-matrix-column-names P) '("dose" "age")
> (table->design-matrix patients) table->design-matrix: the table has an element that is not a
real number
column: "id"
row: 0
element: "a"
> (table->design-matrix patients '("age" "weight")) table->design-matrix: the table has no column with this name
column: "weight"
columns of the table: '("age" "dose" "id")
2.3 Nested lists and vectors
| (require glmnet/data/nested) | package: glmnet |
Racket’s own data for a design matrix is a list or a vector of rows, each row a list or a vector. Every fit and prediction procedure accepts these four nestings as they are (see design-matrix/c). This module converts them to a design-matrix? value, to check the data once and fit it many times or to name its columns, and converts a design matrix back to any of them. A response needs no conversion of its own: a list, vector, flvector or f64vector is accepted wherever a response is (see response/c and response->f64vector). glmnet does not re-export this module.
rows->design-matrix and columns->design-matrix are the list-of-lists cases of nested->design-matrix. The three read their input the same way, so the same entries give equal? design matrices, and so do the fits and predictions on them.
procedure
(nested->design-matrix xss [ #:by by #:column-names column-names]) → design-matrix?
xss :
(or/c (listof (or/c list? vector?)) (vectorof (or/c list? vector?))) by : (or/c 'rows 'columns) = 'rows column-names : (or/c #f (listof (or/c string? symbol?))) = #f
> (require glmnet/data/nested) > (define vrows (vector #(1.0 4.0) #(2.0 5.0) #(3.0 6.0))) > (define V (nested->design-matrix vrows)) > (design-matrix->rows V) '((1.0 4.0) (2.0 5.0) (3.0 6.0))
> (equal? V (nested->design-matrix (list #(1 2 3) '(4 5 6)) #:by 'columns)) #t
> (equal? V (rows->design-matrix '((1 4) (2 5) (3 6)))) #t
> (design-matrix-column-names (nested->design-matrix vrows #:column-names '(x z))) '("x" "z")
> (nested->design-matrix (vector #(1.0 2.0) #(3.0))) nested->design-matrix: the matrix has rows of different
lengths
row: 1
length: 1
length of row 0: 2
procedure
(design-matrix->nested dm [ #:by by #:outer outer #:inner inner]) → (or/c list? vector?) dm : design-matrix? by : (or/c 'rows 'columns) = 'rows outer : (or/c 'list 'vector) = 'list inner : (or/c 'list 'vector) = 'list
> (design-matrix->nested V #:outer 'vector #:inner 'vector) '#(#(1.0 4.0) #(2.0 5.0) #(3.0 6.0))
> (design-matrix->nested V #:inner 'vector) '(#(1.0 4.0) #(2.0 5.0) #(3.0 6.0))
> (design-matrix->nested V #:by 'columns #:outer 'vector) '#((1.0 2.0 3.0) (4.0 5.0 6.0))
> (equal? (design-matrix->nested V) (design-matrix->rows V)) #t
2.4 CSV files
| (require glmnet/data/csv) | package: glmnet |
glmnet/data/csv reads and writes tables as CSV files, following RFC 4180. glmnet does not re-export it. See CSV files.
When reading, the input must be UTF-8. The first record is the header, whose cells name the columns: each name must be non-empty and appear once. Records end with a line feed, a carriage return or both, and the last one need not; a byte-order mark at the start is skipped. A cell in double quotes can hold commas, line breaks and double quotes, which are written twice. Every record must have one cell per column.
Each cell is typed on its own, as R’s read.csv types a column that holds only that cell:
A cell is missing when it is NA, quoted or not, or when it is not quoted and is empty or holds only white space. A missing cell is an error.
A number is a flonum. A number is a decimal number, such as 3, -2.5, .5, 5. or 1e-3; a hexadecimal one, such as 0x1A, 0x.8 or 0x1.8p1; or Inf, Infinity or NaN, in any case; each with an optional sign. White space around a number is ignored. A number is rounded correctly, however many digits it has, which R’s reader does not always do for a decimal number. -0 is -0.0, where R reads it as the integer 0.
TRUE and T are #t, and FALSE and F are #f. Other spellings, such as true or False, are strings, as they are in R.
Any other cell is a string, as it is written between the quotes, white space included: " TRUE" and "NA " are strings, as they are in R, and "" is the empty string.
White space is what R takes as white space in a UTF-8 locale: space, tab, line feed, vertical tab, form feed and carriage return, and the Unicode spaces U+1680, U+2000 to U+2006, U+2008 to U+200A, U+2028, U+2029, U+205F and U+3000, but not the no-break spaces U+00A0, U+2007 and U+202F. It makes a cell blank, and it can follow a number; before a number, only the ASCII white space is skipped, as in R. In the C locale R takes only the ASCII white space, and reads a cell of Unicode spaces as a string.
Quotes change the value of a cell only when it is empty or holds only white space: then it is a string when it is quoted, and missing when it is not, where R reads both as missing. A number, a logical or NA is the same with or without quotes, as in R. Unlike R, which gives a whole column one type, a column can mix kinds: a column of the letters A, C, G and T, which R reads as strings, holds three strings and #t, and a formula that reads it raises an error naming the column. R’s complex numbers, such as 1i, are strings.
The table is an association list from each name, a string, to its column, a vector, in the header’s order. An error names the procedure called, the column, the row, counting from 0, and the line of the input on which the row starts, counting from 1, and the file when there is one. Input that is not UTF-8 is an error that names the line and the offset of its first byte that is not, counting from 0.
When writing, the header is the table’s column names, in its order, and then there is one line per row, each ended by a line feed; a table whose columns are empty is its header alone. A real is written as the shortest decimal that reads back as the same flonum, without a trailing .0; an infinity as Inf or -Inf, as R writes it; and a NaN as NaN, which R reads back as NaN, where R’s write.csv writes NA. A boolean is TRUE or FALSE, and a string, or a symbol’s name, is written as it is. A cell or a name is quoted when it holds a comma, a double quote or a line break, starts or ends with white space or starts with a byte-order mark, or is empty, and a string is also quoted when it would read as another value, such as "42" or "T", as R’s write.csv quotes every string. It still reads back as that value, as it does in R. A string that would read back as a missing value, "NA", cannot be written, nor can a value of another kind or a column without a name; an error names the column and the row.
procedure
(csv->table [in]) → table?
in : input-port? = (current-input-port)
> (require glmnet/data/csv) > (csv->table (open-input-string "id,dose,treated\nA,2.5,TRUE\n\"B, 2\",5,F\n")) '(("id" . #("A" "B, 2")) ("dose" . #(2.5 5.0)) ("treated" . #(#t #f)))
> (csv->table (open-input-string "note\n\"said \"\"hi\"\"\"\n\"two\nlines\"\n")) '(("note" . #("said \"hi\"" "two\nlines")))
> (csv->table (open-input-string "x\n0x1A\n-inf\n 7 \n\" TRUE\"\ntrue\n")) '(("x" . #(26.0 -inf.0 7.0 " TRUE" "true")))
> (csv->table (open-input-string "x,y\n1,2\n3,NA\n")) csv->table: the input has a missing value
column: "y"
row: 1
line: 3
> (csv->table (open-input-string "x\n1 \n \n")) csv->table: the input has a missing value
column: "x"
row: 1
line: 3
> (csv->table (open-input-bytes #"name\nM\374ller\n")) csv->table: the input is not UTF-8
line: 2
byte offset: 6
procedure
(csv-file->table path) → table?
path : path-string?
> (define mtcars-file (collection-file-path "mtcars.csv" "glmnet" "datasets")) > (map car (csv-file->table mtcars-file)) '("mpg" "cyl" "disp" "hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
procedure
(table->csv table [out]) → void?
table : table? out : output-port? = (current-output-port)
> (table->csv (list (cons "x" (list 1 0.1 1/3 +inf.0)) (cons "label" '("a" "b, c" "42" say)) (cons "flag" '(#t #f #t #f))))
x,label,flag
1,a,TRUE
0.1,"b, c",FALSE
0.3333333333333333,"42",TRUE
Inf,say,FALSE
> (define out (open-output-string)) > (table->csv (list (cons "x" (list 0.1 (+ 0.1 0.2) 1e-300))) out) > (get-output-string out) "x\n0.1\n0.30000000000000004\n1e-300\n"
> (csv->table (open-input-string (get-output-string out))) '(("x" . #(0.1 0.30000000000000004 1e-300)))
> (table->csv (csv->table (open-input-string "id,dose\n"))) id,dose
> (table->csv (list (cons "code" '("NA" "b")))) table->csv: the table has a string that would be read back
as a missing value
column: "code"
row: 0
element: "NA"
procedure
(table->csv-file table path [#:exists exists]) → void?
table : table? path : path-string?
exists : (or/c 'error 'replace 'truncate 'truncate/replace) = 'error
> (define path (make-temporary-file "table-~a.csv")) > (table->csv-file (list (cons "x" '(1 2)) (cons "y" '(3.5 4.5))) path #:exists 'replace) > (file->string path) "x,y\n1,3.5\n2,4.5\n"
> (csv-file->table path) '(("x" . #(1.0 2.0)) ("y" . #(3.5 4.5)))
2.5 Matrices from math/matrix
| (require glmnet/data/math) | package: glmnet |
Conversions between the matrices of math/matrix and design matrices, and from math/array arrays to responses. The rows of a matrix are observations and its columns predictors. glmnet does not re-export these bindings, and (require glmnet) does not load math/matrix. See Matrices from math/matrix.
Every array that math/array returns to untyped code carries a contract, and so does the procedure that computes its elements, which checks the index it is called with each time. The conversions’ element loops are written in Typed Racket, so they call that procedure without adding contracts of their own, and they avoid it where they can. The design matrix is written in place, with no intermediate copy:
a flonum array (an FlArray, from array->flarray, flarray or design-matrix->matrix) is copied from its flarray-data in one pass;
a mutable array (a Mutable-Array, from vector->matrix or array->mutable-array) is read from its mutable-array-data;
any other array, such as the result of build-matrix, matrix or matrix*, is read one element at a time through its contracted procedure;
a lazy array, one made while array-strictness is #f or one that array-broadcast or array-lazy returns, which are lazy at the default setting too, is read the same way, with a fresh mutable index vector for each element, because its index transforms, such as those of matrix-transpose and array-slice-ref, write to the vector they are given.
For a large matrix, the first two take about as long as rows->design-matrix takes for the same rows as lists, the third several times as long, and the fourth far longer.
procedure
(matrix->design-matrix M [ #:column-names column-names]) → design-matrix? M : (and/c array? matrix?) column-names : (or/c #f (listof (or/c string? symbol?))) = #f
> (require math/array math/matrix glmnet/data/math) > (define M (matrix [[1 2 3] [2 1 5] [3 4 11] [4 3 11] [5 6 17]])) > (define D (matrix->design-matrix M #:column-names '(x1 x2 y))) > (design-matrix->rows D) '((1.0 2.0 3.0) (2.0 1.0 5.0) (3.0 4.0 11.0) (4.0 3.0 11.0) (5.0 6.0 17.0))
> (equal? D (rows->design-matrix (matrix->list* M) #:column-names '(x1 x2 y))) #t
> (coef (formula-fit (~ y x1 x2) D #:lambda 0))
'(("(Intercept)" . -1.0345797337849323)
("x1" . 2.234820972582017)
("x2" . 1.1656615050121506))
> (matrix->design-matrix (matrix [[1.0 2.0] [3.0 +nan.0]]) #:column-names '(x1 x2)) matrix->design-matrix: the matrix has an element that is not
finite
column: "x2"
row: 1
element: +nan.0
procedure
(design-matrix->matrix dm) → (and/c array? matrix?)
dm : design-matrix?
> (design-matrix->matrix D)
(flarray
#[#[1.0 2.0 3.0]
#[2.0 1.0 5.0]
#[3.0 4.0 11.0]
#[4.0 3.0 11.0]
#[5.0 6.0 17.0]])
> (equal? (matrix->design-matrix (design-matrix->matrix D)) (matrix->design-matrix M)) #t
> (matrix* (design-matrix->matrix (rows->design-matrix '((1 2) (3 4)))) (col-matrix [1 -1])) (array #[#[-1.0] #[-1.0]])
procedure
(array->response A) → (and/c (listof real?) pair?)
A :
(and/c array? (or/c row-matrix? col-matrix? (property/c array-shape (vector/c exact-positive-integer?))))
> (array->response (col-matrix [1 0 1])) '(1 0 1)
> (array->response (row-matrix [2.5 1/2])) '(2.5 1/2)
> (array->response (array #[0 2 1])) '(0 2 1)
> (lasso (matrix->design-matrix M) (array->response (->col-matrix '(1 3 2 5 4))) #:lambda 0.1) #<glmnet:gaussian λ=0.1 dev=0.9170 nz=2/3>
> (array->response (matrix [[1 2] [3 4]])) array->response: contract violation
expected: (and/c array? (or/c row-matrix? col-matrix?
(property/c array-shape (vector/c
exact-positive-integer?))))
given: (array #[#[1 2] #[3 4]])
in: the 1st argument of
(->
(and/c
array?
(or/c
row-matrix?
col-matrix?
(property/c
array-shape
(vector/c exact-positive-integer?))))
(non-empty-listof real?))
contract from: <pkgs>/glmnet/data/math.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/data/math.rkt:123:3
2.6 Polars dataframes
| (require glmnet/data/polars) | package: glmnet |
Conversions between the dataframes of polars and glmnet’s design matrices, responses and tables. glmnet does not re-export them and does not load Polars. See Polars dataframes.
A column that is converted to numbers must have an integer or floating-point dtype; Polars casts it to doubles as it copies it out. Column names are strings or symbols, compared as strings, and must be names of the dataframe’s columns; the contracts check the names and the dtypes. A missing value (a null), anywhere in a column that is converted, is an error naming its column and row, and so is a value that is not finite where numbers are needed. Nothing is dropped or filled in.
procedure
(polars->design-matrix df columns) → design-matrix?
df : dataframe? columns : (and/c (listof (or/c string? symbol?)) pair?)
> (define trial (dataframe (list (series '(1 2 3) #:name "dose") (series '(0.5 1.5 2.5) #:name "age") (series '("a" "b" "a") #:name "site")))) > (define trial-matrix (polars->design-matrix trial '(age "dose"))) > (design-matrix->rows trial-matrix) '((0.5 1.0) (1.5 2.0) (2.5 3.0))
> (design-matrix-column-names trial-matrix) '("age" "dose")
> (polars->design-matrix trial '("dose" "site")) polars->design-matrix: contract violation
expected: a non-empty list of distinct names of numeric
columns of the dataframe
given: column "site", of dtype string
in: the columns argument of
(->i
((df
(and/c dataframe? dataframe-with-rows/c))
(columns
(df)
(frame-columns/c
df
numeric-dtype?
"numeric")))
(result design-matrix?))
contract from: <pkgs>/glmnet/data/polars.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/data/polars.rkt:22:3
procedure
(design-matrix->polars dm [ #:column-names column-names]) → dataframe? dm : design-matrix?
column-names : (listof (or/c string? symbol?)) =
(or (design-matrix-column-names dm) (list "V1" "V2" ...))
> (design-matrix->polars trial-matrix)
shape: (3, 2)
┌─────┬──────┐
│ age ┆ dose │
│ --- ┆ --- │
│ f64 ┆ f64 │
╞═════╪══════╡
│ 0.5 ┆ 1.0 │
│ 1.5 ┆ 2.0 │
│ 2.5 ┆ 3.0 │
└─────┴──────┘
> (column-names (design-matrix->polars (rows->design-matrix '((1 2))))) '("V1" "V2")
> (column-names (design-matrix->polars trial-matrix #:column-names '(a b))) '("a" "b")
procedure
(polars->response df column) → (and/c (listof real?) pair?)
df : dataframe? column : (or/c string? symbol?)
> (polars->response trial "dose") '(1 2 3)
> (polars->response (dataframe (list (series (list 1.0 polars-null 3.0) #:name "y"))) "y") polars->response: the dataframe has a missing value
column: "y"
row: 1
procedure
(polars->table df [columns]) → table?
df : dataframe?
columns : (and/c (listof (or/c string? symbol?)) pair?) = (column-names df)
> (polars->table trial) '(("dose" . #(1 2 3)) ("age" . #(0.5 1.5 2.5)) ("site" . #("a" "b" "a")))
> (polars->table trial '("site")) '(("site" . #("a" "b" "a")))
procedure
(table->polars t [columns]) → dataframe?
t : table?
columns : (and/c (listof (or/c string? symbol?)) pair?) = (table-column-names t)
'int64 for exact integers from −263 to 263 − 1;
'uint64 for exact integers from 0 to 264 − 1, when some are 263 or more;
'float64 for any other reals, and for integers mixed with them;
'boolean for booleans, 'categorical for symbols, and 'string for strings, or for strings and symbols mixed.
> (define cars (table->polars mtcars '("mpg" "cyl" "wt"))) > (map (lambda (name) (dtype (ref cars name))) (column-names cars)) '(float64 float64 float64)
> (table->polars (list (cons "id" '(a b a)) (cons "x" '(1 2.5 3))))
shape: (3, 2)
┌─────┬─────┐
│ id ┆ x │
│ --- ┆ --- │
│ cat ┆ f64 │
╞═════╪═════╡
│ a ┆ 1.0 │
│ b ┆ 2.5 │
│ a ┆ 3.0 │
└─────┴─────┘
> (dtype (ref (table->polars (list (cons "n" (list 1 (expt 2 63))))) "n")) 'uint64
> (table->polars (list (cons "x" '(1 "two")))) table->polars: the table has a column whose values no Polars
dtype holds
column: "x"
row: 1
element: "two"
2.7 Example datasets
| (require glmnet/datasets) | package: glmnet |
glmnet/datasets provides the example datasets of R’s glmnet 4.1.10, which its vignettes use, and R’s mtcars and iris, which the formula examples use. glmnet does not re-export it. See Example datasets.
A dataset is a CSV file in the package, under "glmnet/datasets/", which "scripts/export-datasets.R" writes from R with 17 significant digits, so that every number reads back as R’s double. R glmnet’s datasets have a procedure each, which reads its file on its first call and returns the same values on every call. The values are the arguments of the family’s fitter, in order: the predictors as a design matrix whose columns are named "V1", "V2", and so on, as R’s coef names the columns of these unnamed matrices, and then the response, in the shape the family takes (see Data). mtcars and iris are tables, read when the module is instantiated. Every module that requires them shares them, so their columns are immutable vectors; csv-file->table reads a fresh copy whose columns can be changed.
procedure
(quick-start-example) →
design-matrix? (listof flonum?)
> (require glmnet/datasets) > (define-values (x y) (quick-start-example)) > x #<design-matrix 100x20>
> (length y) 100
> (lasso x y #:lambda 0.1) #<glmnet:gaussian λ=0.1 dev=0.8994 nz=9/20>
procedure
(binomial-example) →
design-matrix? (listof (or/c 0 1))
> (define-values (bx by) (binomial-example)) > (list (design-matrix-nrows bx) (design-matrix-ncols bx)) '(100 30)
> (for/sum ([label (in-list by)]) label) 56
procedure
(multinomial-example) →
design-matrix? (listof (or/c 0 1 2))
> (define-values (mx my) (multinomial-example))
> (for/list ([k (in-range 3)]) (for/sum ([label (in-list my)]) (if (= label k) 1 0))) '(142 174 184)
procedure
(poisson-example) →
design-matrix? (listof exact-nonnegative-integer?)
> (define-values (px py) (poisson-example)) > (apply max py) 395
procedure
(cox-example) →
design-matrix? (listof (and/c flonum? positive?)) (listof (or/c 0 1))
> (define-values (cx time status) (cox-example)) > (for/sum ([s (in-list status)]) s) 692
> (cox-path cx time status #:nlambda 5)
#<glmnet-path:cox
Df %Dev Lambda
1 0 0.00 0.236800
2 13 5.62 0.023680
3 25 5.87 0.002368
4 29 5.87 0.000237
5 30 5.87 0.000024>
procedure
(multi-gaussian-example) →
design-matrix? design-matrix?
> (define-values (gx gy) (multi-gaussian-example)) > (design-matrix-column-names gy) '("y1" "y2" "y3" "y4")
procedure
(sparse-example) →
design-matrix? (listof flonum?)
> (define-values (sx sy) (sparse-example))
> (for*/sum ([row (in-list (design-matrix->rows sx))] [v (in-list row)]) (if (zero? v) 1 0)) 1678
> (table-column-names mtcars) '("mpg" "cyl" "disp" "hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
> (cdr (assoc "wt" mtcars))
'#(2.62
2.875
2.32
3.215
3.44
3.46
3.57
3.19
3.15
3.44
3.44
4.07
3.73
3.78
5.25
5.424
5.345
2.2
1.615
1.835
2.465
3.52
3.435
3.84
3.845
1.935
2.14
1.513
3.17
2.77
3.57
2.78)
> (vector-set! (cdr (assoc "wt" mtcars)) 0 3.0) vector-set!: contract violation
expected: (and/c vector? (not/c immutable?))
given: '#(2.62 2.875 2.32 3.215 3.44 3.46 3.57 3.19 3.15
3.44 3.44 4.07 3.73 3.78 5.25 5.424 5.345 2.2 1.615 1.835
2.465 3.52 3.435 3.84 3.845 1.935 2.14 1.513 3.17 2.77 3.57
2.78)
> (table-column-names iris) '("Sepal.Length" "Sepal.Width" "Petal.Length" "Petal.Width" "Species")
> (formula-predictor-names (Sepal.Length . ~ . Petal.Width + Species) iris) '("Petal.Width" "Speciesversicolor" "Speciesvirginica")
2.8 Gaussian models
The Gaussian family. The four named models are elnet-fit with a fixed #:alpha. See Ordinary least squares (λ = 0), Ridge regression (L2, α = 0), Lasso (L1, α = 1) and Elastic net (0 < α < 1).
struct
(struct elnet-result ( intercept coefficients r-squared lambda num-passes) #:transparent) intercept : real? coefficients : (vectorof real?) r-squared : real? lambda : real? num-passes : exact-nonnegative-integer?
Like every result type, it prints as a summary of its family, λ, deviance ratio and number of nonzero coefficients (see Printing), and it implements gen:glmnet-model.
> (define X '((1.0 2.0 1.0) (2.0 1.0 4.0) (3.0 4.0 9.0) (4.0 3.0 16.0) (5.0 6.0 25.0) (6.0 5.0 36.0))) > (define y '(1.0 4.0 3.0 6.0 5.0 8.0)) > (define fit (lasso X y #:lambda 0.05)) > fit #<glmnet:gaussian λ=0.05 dev=0.9941 nz=2/3>
> (elnet-result-intercept fit) 0.9999999999999996
> (elnet-result-coefficients fit) '#(1.8292174872340037 -0.8292174872340038 0.0)
procedure
(elnet-fit X y [ #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → elnet-result? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (elnet-fit X y #:alpha 0.5 #:lambda 0.5) #<glmnet:gaussian λ=0.5 dev=0.7838 nz=2/3>
> (elnet-fit autos "mpg" #:predictors '("wt" "hp") #:alpha 0.5 #:lambda 0.5) #<glmnet:gaussian λ=0.5 dev=0.8434 nz=2/2>
> (lasso X '(2.0 2.0 2.0 2.0 2.0 2.0) #:lambda 0.5) lasso: y is constant; gaussian glmnet fails at
standardization step
procedure
(ols X y [ #:predictors predictors #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → elnet-result? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-10 max-iters : exact-positive-integer? = 100000
> (elnet-result-coefficients (ols '((1.0 2.0) (2.0 1.0) (3.0 4.0) (4.0 3.0) (5.0 6.0)) '(1.0 4.0 3.0 6.0 5.0))) '#(1.9999829127580482 -0.9999884545662485)
> (elnet-result-coefficients (ols autos "mpg" #:predictors '("wt" "hp"))) '#(-2.5190175381213304 -0.030876933077271105)
procedure
(ridge X y [ #:predictors predictors] #:lambda lambda [ #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → elnet-result? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f lambda : (>=/c 0) standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (elnet-result-coefficients (ridge X y #:lambda 0.1)) '#(1.1614345231080536 -0.7532810830027743 0.08306586531538782)
> (elnet-result-coefficients (ridge autos "mpg" #:predictors '("wt" "hp") #:lambda 1.0)) '#(-2.2279325497635045 -0.02388297752938169)
procedure
(lasso X y [ #:predictors predictors] #:lambda lambda [ #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → elnet-result? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f lambda : (>=/c 0) standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (elnet-result-coefficients (lasso X y #:lambda 0.5)) '#(0.8786585495440113 0.0 0.0)
> (elnet-result-coefficients (lasso autos "mpg" #:predictors '("wt" "hp") #:lambda 1.0)) '#(-1.2137877816701421 -0.019538683227314706)
procedure
(elastic-net X y [ #:predictors predictors] #:alpha alpha #:lambda lambda [ #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → elnet-result? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f alpha : (real-in 0 1) lambda : (>=/c 0) standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (elnet-result-coefficients (elastic-net X y #:alpha 0.5 #:lambda 0.5)) '#(0.5773773035370475 0.0 0.054686809526739884)
> (elnet-result-coefficients (elastic-net autos "mpg" #:predictors '("wt" "hp") #:alpha 0.5 #:lambda 1.0)) '#(-1.8006845871692458 -0.02166964237447535)
procedure
(elnet-predict fit X) → (listof real?)
fit : elnet-result? X : data/c
> (elnet-predict fit '((7.0 6.0 49.0) (0.0 0.0 0.0))) '(8.829217487234002 0.9999999999999996)
> (elnet-predict car-fit (list (cons "wt" '(3.0 2.5)) (cons "hp" '(150 100)))) '(19.326669351755836 22.130024774680052)
2.9 Binomial models
The binomial family: two-class logistic regression on 0/1 labels. See Binomial logistic regression (classification).
struct
(struct logistic-result ( intercept coefficients dev-ratio lambda num-passes) #:transparent) intercept : real? coefficients : (vectorof real?) dev-ratio : real? lambda : real? num-passes : exact-nonnegative-integer?
> (require glmnet/datasets)
> (define X '((1.0 5.0 2.0) (2.0 6.0 1.0) (2.0 5.0 3.0) (1.0 4.0 1.0) (6.0 2.0 2.0) (5.0 1.0 1.0) (6.0 1.0 3.0) (5.0 2.0 1.0))) > (define y '(0 0 0 0 1 1 1 1)) > (define fit (logistic-fit X y #:lambda 0.05)) > (logistic-result-coefficients fit) '#(0.9597305669295235 -0.5738296629445224 0.0)
> (logistic-result-dev-ratio fit) 0.9168013564414029
procedure
(logistic-fit X y [ #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → logistic-result? X : data/c y : (response-for/c X (or/c 0 1) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (logistic-fit X y #:lambda 0.05) #<glmnet:binomial λ=0.05 dev=0.9168 nz=2/3>
> (define cars+ (cons (cons "heavy" (for/list ([wt (in-vector (cdr (assoc "wt" mtcars)))]) (if (> wt 3.3) "yes" "no"))) mtcars)) > (define heavy-fit (logistic-fit cars+ "heavy" #:predictors '("mpg" "hp") #:lambda 0.05)) > (logistic-predict heavy-fit (hash "mpg" '(15.0 30.0) "hp" '(200 70))) '("yes" "no")
> (logistic-fit iris "Species" #:lambda 0.05 #:predictors '("Petal.Length" "Petal.Width")) logistic-fit: a binomial response has two classes; the
multinomial family takes more
column: "Species"
classes: '("setosa" "versicolor" "virginica")
procedure
(logistic-predict-proba fit X) → (listof (real-in 0 1))
fit : logistic-result? X : data/c
> (logistic-predict-proba fit '((2.0 5.0 2.0) (5.0 2.0 2.0))) '(0.0829824131519593 0.9000862010987204)
procedure
(logistic-predict fit X [ #:threshold threshold]) → (listof (or/c 0 1 string?)) fit : logistic-result? X : data/c threshold : (real-in 0 1) = 0.5
> (logistic-predict fit '((2.0 5.0 2.0) (5.0 2.0 2.0))) '(0 1)
2.10 Multinomial models
The multinomial family: K-class logistic regression on integer labels. See Multinomial classification (K classes).
struct
(struct multinomial-result ( intercepts coefficients dev-ratio lambda num-passes) #:transparent) intercepts : (vectorof real?) coefficients : (vectorof (vectorof real?)) dev-ratio : real? lambda : real? num-passes : exact-nonnegative-integer?
> (require glmnet/datasets) > (define X '((1.0 1.0) (2.0 1.0) (5.0 1.0) (6.0 1.0) (3.0 5.0) (4.0 6.0))) > (define y '(0 0 1 1 2 2)) > (define fit (multinomial-fit X y #:lambda 0.05)) > (multinomial-result-coefficients fit)
'#(#(-0.6863780549780656 0.0)
#(0.8092663108066648 0.0)
#(0.0 1.140531561288397))
procedure
(multinomial-fit X y [ #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → multinomial-result? X : data/c y : (response-for/c X (and/c integer? (>=/c 0)) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (multinomial-result-intercepts (multinomial-fit X y #:lambda 0.05)) '#(3.497091517940383 -1.7181551950723566 -1.778936322868027)
> (multinomial-result-intercepts (multinomial-fit X '(a a b b c c) #:lambda 0.05)) '#(3.497091517940383 -1.7181551950723566 -1.778936322868027)
> (multinomial-result-intercepts (multinomial-fit iris "Species" #:predictors '("Petal.Length" "Petal.Width") #:lambda 0.05)) '#(4.756583464635003 0.3567756057814526 -5.113359070416457)
> (multinomial-fit X '(0 0 2 2 2 2) #:lambda 0.05) multinomial-fit: class 1 has no observations; labels must
cover 0..2 contiguously
procedure
(multinomial-predict-proba fit X)
→ (listof (listof (real-in 0 1))) fit : multinomial-result? X : data/c
> (multinomial-predict-proba fit '((1.5 1.0) (3.5 5.5)))
'((0.912412962930536 0.046726550367775885 0.04086048670168831)
(0.03128871441725081 0.03190510530876551 0.9368061802739837))
procedure
(multinomial-predict fit X)
→ (listof (or/c exact-nonnegative-integer? string?)) fit : multinomial-result? X : data/c
> (multinomial-predict fit '((1.5 1.0) (5.5 1.0) (3.5 5.5))) '(0 1 2)
2.11 Cox models
The Cox family: proportional-hazards survival models. There is no intercept, and so no #:intercept? keyword. See Cox proportional hazards (survival).
struct
(struct cox-result (coefficients dev-ratio lambda num-passes) #:transparent) coefficients : (vectorof real?) dev-ratio : real? lambda : real? num-passes : exact-nonnegative-integer?
> (define X '((0.5 1.0) (1.0 2.0) (1.5 1.0) (2.0 2.0) (2.5 1.0) (3.0 2.0) (3.5 1.0) (4.0 2.0))) > (define times '(12.0 10.0 11.0 8.0 6.0 7.0 4.0 3.0)) > (define statuses '(0 0 0 1 1 1 1 1)) > (define fit (cox-fit X times statuses #:lambda 0.1)) > (cox-result-coefficients fit) '#(1.9229529670643517 0.0)
procedure
(cox-fit X y [ statuses #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:thresh thresh #:max-iters max-iters]) → cox-result? X : data/c y : (survival-for/c X) statuses : (statuses-for/c X y) = none predictors : (predictors-for/c X y) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (cox-fit X times statuses #:lambda 0.5) #<glmnet:cox λ=0.5 dev=0.2367 nz=1/2>
> (define patients (list (cons "age" '(50 61 45 70 58 66 39 72)) (cons "dose" '(1.0 2.0 1.0 2.0 1.0 2.0 1.0 2.0)) (cons "months" times) (cons "died" statuses))) > (cox-fit patients '("months" "died") #:predictors '("age" "dose") #:lambda 0.05) #<glmnet:cox λ=0.05 dev=0.0385 nz=1/2>
> (cox-fit patients '("months") #:predictors '("age") #:lambda 0.5) cox-fit: contract violation
expected: a list of the names of two columns of the table,
the time and the status
given: '("months"), a list of one name
in: the y argument of
(->*
(data/c
(survival-for/c X)
#:lambda
(>=/c 0))
((statuses-for/c X y)
#:predictors
(predictors-for/c X y)
...)
cox-result?)
contract from: <pkgs>/glmnet/core/cox.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/cox.rkt:32:3
> (cox-fit X times '(0 0 0 0 0 0 0 0) #:lambda 0.1) cox-fit: at least one observation must be an event (status =
1)
procedure
(cox-linear-predictor fit X) → (listof real?)
fit : cox-result? X : data/c
> (cox-linear-predictor fit '((1.0 1.0) (3.0 1.0))) '(1.9229529670643517 5.768858901193055)
procedure
(cox-relative-risk fit X) → (listof (>/c 0))
fit : cox-result? X : data/c
> (cox-relative-risk fit '((1.0 1.0) (3.0 1.0))) '(6.8411303037210045 320.17217603082736)
2.12 Poisson models
The Poisson family: counts with a log link. See Poisson regression (counts).
struct
(struct poisson-result ( intercept coefficients dev-ratio lambda num-passes) #:transparent) intercept : real? coefficients : (vectorof real?) dev-ratio : real? lambda : real? num-passes : exact-nonnegative-integer?
> (require glmnet/datasets)
> (define X '((1.0 2.0) (2.0 1.0) (3.0 2.0) (4.0 1.0) (5.0 2.0) (6.0 1.0) (7.0 2.0) (8.0 1.0))) > (define y '(1 2 2 3 4 6 8 11)) > (define fit (poisson-fit X y #:lambda 0.2)) > (poisson-result-intercept fit) -0.026590920441019072
> (poisson-result-coefficients fit) '#(0.29703115403010283 0.0)
procedure
(poisson-fit X y [ #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → poisson-result? X : data/c y : (response-for/c X (>=/c 0)) predictors : (predictors-for/c X y) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (poisson-fit X y #:lambda 0.5) #<glmnet:poisson λ=0.5 dev=0.9596 nz=1/2>
> (poisson-fit mtcars "carb" #:predictors '("hp" "wt") #:lambda 0.1) #<glmnet:poisson λ=0.1 dev=0.5426 nz=1/2>
> (poisson-fit X '(0 0 0 0 0 0 0 0) #:lambda 0.5) poisson-fit: the response has no positive count; Poisson
needs at least one y > 0
procedure
(poisson-predict-mean fit X) → (listof (>/c 0))
fit : poisson-result? X : data/c
> (poisson-predict-mean fit '((2.0 1.0) (9.0 1.0))) '(1.7638014377572937 14.107258692835407)
2.13 Multi-response Gaussian models
The multi-response Gaussian family: several numeric responses fitted jointly under a grouped penalty. See Multi-response Gaussian (grouped).
struct
(struct mgaussian-result ( intercepts coefficients r-squared lambda num-passes) #:transparent) intercepts : (vectorof real?) coefficients : (vectorof (vectorof real?)) r-squared : real? lambda : real? num-passes : exact-nonnegative-integer?
> (require glmnet/datasets) > (define X '((1.0 2.0) (2.0 1.0) (3.0 2.0) (4.0 1.0) (5.0 2.0) (6.0 1.0))) > (define Y '((3.0 9.0) (5.0 8.0) (7.0 7.0) (9.0 6.0) (11.0 5.0) (13.0 4.0))) > (define fit (mgaussian-fit X Y #:lambda 0.1)) > (mgaussian-result-intercepts fit) '#(1.1833030277982335 9.908348486100884)
> (mgaussian-result-coefficients fit) '#(#(1.9476277063433618 0.0) #(-0.9738138531716809 0.0))
procedure
(mgaussian-fit X Y [ #:predictors predictors] #:lambda lambda [ #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → mgaussian-result? X : data/c Y : (responses-for/c X) predictors : (predictors-for/c X Y) = #f lambda : (>=/c 0) alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (mgaussian-fit X Y #:lambda 0.5) #<glmnet:mgaussian λ=0.5 dev=0.9829 nz=1/2>
> (mgaussian-result-coefficients (mgaussian-fit mtcars '("mpg" "qsec") #:predictors '("wt" "hp") #:lambda 0.5))
'#(#(-3.4767908843263777 -0.029324767934641435)
#(0.4859581017233457 -0.018998204010102826))
procedure
(mgaussian-predict fit X) → (listof (listof real?))
fit : mgaussian-result? X : data/c
> (mgaussian-predict fit '((7.0 1.0) (8.0 2.0)))
'((14.816696972201767 3.0916515138991176)
(16.76432467854513 2.117837660727437))
2.14 Regularization paths
A regularization path fits a decreasing sequence of λ in one call. Every family has a path fitter, and they all return a glmnet-path. Each fitter takes its family’s data arguments and keywords, with #:lambda made optional:
#:lambda is a list of penalties, fitted largest first. When it is #f (the default), glmnet chooses the sequence as R does: #:nlambda values from λmax, where every coefficient is zero, down to #:lambda-min-ratio times λmax. The ratio defaults to 0.01 when there are fewer observations than predictors, and to 0.0001 otherwise; glmnet raises a ratio below 1e-6, including 0, to 1e-6. The first value of an automatic sequence is the extrapolation R’s glmnet reports.
A path can hold fewer λ than asked for, as in R. An automatic sequence stops early once another λ would barely change the fit; the rule depends on the family (below). A binomial or multinomial path, automatic or not, stops where the fitted probabilities saturate at 0 and 1. And any path ends where glmnet fails at one of its λ, for example by not converging within #:max-iters passes: it keeps the λ before that one and logs a warning with the topic 'glmnet (shown with PLTSTDERR="warning@glmnet"), where R warns. The warning names the procedure called: the path fitter, or the cross-validation or formula procedure that called it, with the fold whose training data it was fitting. When glmnet fails at the first λ, the fitter raises exn:fail instead (R returns an empty model).
glmnet’s early-stopping rules apply only to an automatic sequence, and only from its fifth value on. It stops at the λ where, writing D for the deviance ratio:
Gaussian: D gains less than 1e-5 of its own value over the previous λ, or exceeds 0.999.
Multi-response Gaussian: the residual sum of squares falls by less than 1e-5 of its own value, or D exceeds 0.999.
Binomial and multinomial: D gains less than 1e-5 over the previous λ, or exceeds 0.999.
Poisson: D gains less than 0.0001 of its own value over the previous four λ, or exceeds 0.999.
Cox: D gains less than 0.001 of its own value over the previous four λ, or exceeds 0.99.
These are R’s glmnet.control defaults (fdev = 1e-5, devmax = 0.999, mnlam = 5) as each solver applies them.
struct
(struct glmnet-path ( family lambda intercepts coefficients dev-ratio df num-passes) #:transparent) family : (or/c 'gaussian 'binomial 'multinomial 'cox 'poisson 'mgaussian) lambda : (vectorof real?) intercepts : (or/c #f vector?) coefficients : vector? dev-ratio : (vectorof real?) df : (vectorof exact-nonnegative-integer?) num-passes : exact-nonnegative-integer?
intercepts holds a real per λ, or a vector of one real per class or response for the multinomial and multi-response families. Multinomial intercepts are centred to sum to zero, as in multinomial-result. It is #f for Cox, which has no intercept.
coefficients holds a dense vector per λ with one entry per predictor, or a vector of such vectors (one per class or response).
dev-ratio is the fraction of null deviance explained.
df counts the predictors with a nonzero coefficient, in any class or response.
num-passes counts the coordinate-descent passes over the whole path.
A path prints as R prints one: a table with, for each fitted λ, the number of nonzero coefficients (Df), the percentage of null deviance explained (%Dev) and λ itself (see Printing). predict and coef evaluate a path at any λ.
> (require glmnet/datasets)
> (define X '((1.0 2.0 1.0) (2.0 1.0 4.0) (3.0 4.0 9.0) (4.0 3.0 16.0) (5.0 6.0 25.0) (6.0 5.0 36.0))) > (define y '(1.0 4.0 3.0 6.0 5.0 8.0)) > (define path (elnet-path X y #:lambda '(1.0 0.1 0.01))) > path
#<glmnet-path:gaussian
Df %Dev Lambda
1 1 61.07 1.00
2 2 97.63 0.10
3 3 99.98 0.01>
> (glmnet-path-lambda path) '#(1.0 0.1 0.01)
> (glmnet-path-coefficients path)
'#(#(0.5858885276594514 0.0 0.0)
#(1.6584349744677054 -0.6584349744677581 0.0)
#(1.9597271819899955 -0.9658434974467867 0.0008200416386725593))
> (glmnet-path-df path) '#(1 2 3)
procedure
(elnet-path X y [ #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (vector-length (glmnet-path-lambda (elnet-path X y))) 51
> (glmnet-path-df (elnet-path X y #:alpha 0.0 #:nlambda 5)) '#(3 3 3 3 3)
> (glmnet-path-lambda (elnet-path X y #:nlambda 5 #:lambda-min-ratio 0.1))
'#(2.000595149544493
1.1250173275642348
0.6326437348445768
0.35576171622587116
0.2000595149544493)
> (glmnet-path-df (elnet-path autos "mpg" #:predictors '("wt" "hp") #:nlambda 5)) '#(0 2 2 2 2)
> (elnet-path X y #:lambda '(0.1) #:max-iters 1) elnet-path: glmnet fitted no lambda: convergence was not
reached at the first lambda within #:max-iters passes; try a
larger #:max-iters (jerr=-1)
procedure
(logistic-path X y [ #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c y : (response-for/c X (or/c 0 1) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (glmnet-path-df (logistic-path X '(0 0 0 1 1 1) #:lambda '(0.3 0.1 0.03))) '#(1 1 1)
> (glmnet-path-df (logistic-path cars+ "heavy" #:predictors '("mpg" "hp") #:nlambda 5)) '#(0 1 2 2 2)
procedure
(multinomial-path X y [ #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c y : (response-for/c X (and/c integer? (>=/c 0)) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define mpath (multinomial-path X '(0 0 1 1 2 2) #:lambda '(0.3 0.03))) > (vector-ref (glmnet-path-coefficients mpath) 1)
'#(#(-1.2226648880844682 -1.2255649598724434 0.0)
#(0.0 0.0 0.0)
#(0.0 1.0608631342199921 0.1698597888820383))
> (glmnet-path-df (multinomial-path iris "Species" #:nlambda 5 #:predictors '("Petal.Length" "Petal.Width"))) '#(0 2 2 2 2)
procedure
(cox-path X y [ statuses #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c y : (survival-for/c X) statuses : (statuses-for/c X y) = none predictors : (predictors-for/c X y) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define cpath (cox-path X '(12.0 10.0 8.0 6.0 4.0 3.0) '(0 1 1 1 1 1) #:lambda '(0.5 0.05))) > (glmnet-path-coefficients cpath) '#(#(0.353519335866768 0.0 0.0) #(2.336596711472855 0.0 0.0))
> (glmnet-path-df (cox-path patients '("months" "died") #:predictors '("age" "dose") #:lambda '(0.5 0.05))) '#(0 1)
procedure
(poisson-path X y [ #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c y : (response-for/c X (>=/c 0)) predictors : (predictors-for/c X y) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (glmnet-path-df (poisson-path X '(1 2 2 3 5 8) #:lambda '(0.5 0.05))) '#(1 2)
> (glmnet-path-df (poisson-path mtcars "carb" #:predictors '("hp" "wt") #:nlambda 5)) '#(0 1 2 2 2)
procedure
(mgaussian-path X Y [ #:predictors predictors #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-path? X : data/c Y : (responses-for/c X) predictors : (predictors-for/c X Y) = #f lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define gpath (mgaussian-path X '((3.0 9.0) (5.0 8.0) (7.0 7.0) (9.0 6.0) (11.0 5.0) (13.0 4.0)) #:lambda '(1.0 0.1))) > (glmnet-path-intercepts gpath)
'#(#(2.8330302779823358 9.083484861008833)
#(1.1833030277982326 9.908348486100884))
> (glmnet-path-df (mgaussian-path mtcars '("mpg" "qsec") #:predictors '("wt" "hp") #:nlambda 5)) '#(0 2 2 2 2)
2.15 Cross-validation
Every family has a cross-validation procedure, the equivalent of R’s cv.glmnet for that family, and they all return a glmnet-cv. Each takes its family’s data arguments and every keyword of its path fitter, which it passes on to each fit, and these:
#:type-measure is the loss, R’s type.measure. Each family offers R’s choices for it and defaults to R’s default, the first in the table below.
#:nfolds is the number of folds, at least 3 and at most the number of observations. The folds are drawn by random-fold-ids from current-pseudo-random-generator. It is ignored when #:fold-ids is given.
#:fold-ids, R’s foldid, assigns the observations to folds: one fold id per row of X, counting from 0, in a list, vector, flvector, f64vector, math/array array or Polars series, as a response can be. Every id from 0 to the largest must appear, and there must be at least 3 (see fold-ids/c).
#:grouped?, R’s grouped, computes the error and its standard error from the per-fold means when true, and from the per-observation losses otherwise. When the folds average fewer than 3 observations, they are never grouped; 'auc and 'C are always computed per fold; and when the folds average fewer than 10 observations, the Cox deviance is grouped. These adjustments, which R also makes, log a warning with the topic 'glmnet that names the procedure called.
#:lambda is as for the path fitter, but needs at least two values. Every fold’s path is fitted at those values. Without it, each fold’s path chooses its own sequence, as R’s does, and is evaluated at the full-data path’s values by interpolation.
The data are checked before any fold is fitted: the response must have what its family needs, and so must every fold’s training data (each class, or an event). When a fit fails all the same, the error names the cross-validation procedure and says which fit failed: the one to all the data, or the one to the training data of a given held-out fold.
Family |
| Procedure |
| #:type-measure |
Gaussian |
|
| 'mse, 'deviance, 'mae | |
Binomial |
|
| 'deviance, 'class, 'auc, 'mse, 'mae | |
Multinomial |
|
| 'deviance, 'class, 'mse, 'mae | |
Cox |
|
| 'deviance, 'C | |
Poisson |
|
| 'deviance, 'mse, 'mae | |
Multi-response |
|
| 'mse, 'deviance, 'mae |
Choosing λ by cross-validation describes the procedure and each measure. The examples in this section use 60 observations of 8 predictors, of which the first three carry the signal:
> (require glmnet/datasets) > (random-seed 8) > (define (noise) (- (* 2 (random)) 1))
> (define X60 (for/list ([i (in-range 60)]) (for/list ([j (in-range 8)]) (noise)))) > (define beta '(3.0 -2.0 1.0 0.0 0.0 0.0 0.0 0.0))
> (define y60 (for/list ([row (in-list X60)]) (+ 1.0 (for/sum ([b (in-list beta)] [x (in-list row)]) (* b x)) (noise))))
struct
(struct glmnet-cv ( lambda cvm cvsd cvup cvlo nzero measure name path lambda-min lambda-1se index-min index-1se fold-ids) #:transparent) lambda : (vectorof real?) cvm : (vectorof real?) cvsd : (vectorof real?) cvup : (vectorof real?) cvlo : (vectorof real?) nzero : (vectorof exact-nonnegative-integer?) measure : (or/c 'mse 'deviance 'mae 'class 'auc 'C) name : string? path : glmnet-path? lambda-min : real? lambda-1se : real? index-min : exact-nonnegative-integer? index-1se : exact-nonnegative-integer? fold-ids : (listof exact-nonnegative-integer?)
cvm is the cross-validated error, cvsd its standard error, and cvup and cvlo are cvm plus and minus cvsd.
nzero counts the predictors in the model, as R counts them: the path’s glmnet-path-df, except for the multinomial, where it is the median over the classes rounded up, and the multi-response family, where R also counts the first response’s intercept.
A λ at which the standard error is undefined is left out, as R leaves it out; path still holds every fitted λ.
measure is the loss and name R’s name for it. lambda-min is the largest λ at which cvm is smallest, or largest for 'auc and 'C. lambda-1se is the largest λ whose cvm is within cvsd of that best value, with cvsd taken at lambda-min. index-min and index-1se are their positions in lambda, counting from 0. path is the path fitted to all the data, and fold-ids the fold of each observation.
A glmnet-cv implements gen:glmnet-model. Its path is path; predict and coef default to lambda-1se, as R’s predict.cv.glmnet does, and also accept 'lambda-min, 'lambda-1se or any λ; and deviance-ratio is the path’s at lambda-1se. For how it prints, see Printing.
> (define cv (elnet-cv X60 y60)) > cv
#<glmnet-cv:gaussian
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.05424 38 0.3984 0.05967 6
1se 0.16564 26 0.4468 0.06523 3>
> (glmnet-cv-lambda-min cv) 0.054239392702548954
> (vector-ref (glmnet-cv-cvm cv) (glmnet-cv-index-min cv)) 0.3984109992356747
> (coef cv)
'#(0.878293049854064
2.7178140193293583
-1.4713240447178129
0.6956206079817456
0.0
0.0
0.0
0.0
0.0)
> (coef cv #:lambda 'lambda-min)
'#(0.9154747391997028
2.903879277459048
-1.7054265800660615
0.8686835340984955
-0.008767521015963693
-0.11136295679101096
0.0
0.0
-0.0343600088528011)
> (predict cv '((0.5 -0.5 0.0 0.0 0.0 0.0 0.0 0.0))) '(2.9728620818776497)
> (deviance-ratio cv) 0.9109831280347133
procedure
(elnet-cv X y [ #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c y : (response-for/c X real?) predictors : (predictors-for/c X y) = #f type-measure : (or/c 'mse 'deviance 'mae) = 'mse nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (elnet-cv X60 y60 #:type-measure 'mae #:alpha 0.5)
#<glmnet-cv:gaussian
Measure: Mean Absolute Error
Lambda Index Measure SE Nonzero
min 0.05656 45 0.5059 0.04876 6
1se 0.25060 29 0.5471 0.04654 3>
> (define car-cv (elnet-cv mtcars "mpg" #:predictors '("wt" "hp" "qsec") #:fold-ids (for/list ([i (in-range 32)]) (modulo i 4)))) > (coef car-cv) '#(33.36590995019294 -3.150933800516765 -0.0213920284992272 0.0)
> (predict car-cv (list (cons "qsec" '(17.0)) (cons "hp" '(150)) (cons "wt" '(3.0)))) '(20.704304273758567)
> (define halves (for/list ([i (in-range 60)]) (modulo i 2))) > (elnet-cv X60 y60 #:fold-ids halves) elnet-cv: contract violation;
cross-validation needs at least 3 folds
expected: fold ids from 0 to at least 2
given: '(0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0
1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0 1 0
1 0 1 0 1)
in: the #:fold-ids argument of
(->*
(data/c (response-for/c X real?))
(#:predictors (predictors-for/c X y) ...)
glmnet-cv?)
contract from: <pkgs>/glmnet/core/elnet.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/elnet.rkt:86:3
procedure
(logistic-cv X y [ #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c y : (response-for/c X (or/c 0 1) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f
type-measure : (or/c 'deviance 'class 'auc 'mse 'mae) = 'deviance nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define labels (for/list ([v (in-list y60)]) (if (> v 1.0) 1 0))) > (logistic-cv X60 labels #:type-measure 'class)
#<glmnet-cv:binomial
Measure: Misclassification Error
Lambda Index Measure SE Nonzero
min 0.05351 21 0.05000 0.02546 4
1se 0.05872 20 0.06667 0.02722 4>
> (logistic-cv X60 labels #:type-measure 'auc #:nfolds 5)
#<glmnet-cv:binomial
Measure: AUC
Lambda Index Measure SE Nonzero
min 0.03360 26 0.9875 0.01250 4
1se 0.05872 20 0.9812 0.01875 4>
> (define heavy-cv (logistic-cv cars+ "heavy" #:predictors '("mpg" "hp") #:fold-ids (for/list ([i (in-range 32)]) (modulo i 4)))) > (predict heavy-cv (hash "mpg" '(15.0 30.0) "hp" '(200 70)) #:type 'class) '("yes" "no")
procedure
(multinomial-cv X y [ #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c y : (response-for/c X (and/c integer? (>=/c 0)) #:classes? #t) predictors : (predictors-for/c X y #:classes? #t) = #f type-measure : (or/c 'deviance 'class 'mse 'mae) = 'deviance nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define classes (for/list ([v (in-list y60)]) (cond [(< v -0.5) 0] [(< v 2.5) 1] [else 2]))) > (multinomial-cv X60 classes #:type-measure 'class)
#<glmnet-cv:multinomial
Measure: Misclassification Error
Lambda Index Measure SE Nonzero
min 0.009155 39 0.1333 0.04157 4
1se 0.015999 33 0.1667 0.04303 4>
> (multinomial-cv iris "Species" #:predictors '("Petal.Length" "Petal.Width") #:fold-ids (for/list ([i (in-range 150)]) (modulo i 3)) #:type-measure 'class)
#<glmnet-cv:multinomial
Measure: Misclassification Error
Lambda Index Measure SE Nonzero
min 0.08946 18 0.03333 0.01764 1
1se 0.10775 16 0.04667 0.02404 1>
procedure
(cox-cv X y [ statuses #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c y : (survival-for/c X) statuses : (statuses-for/c X y) = none predictors : (predictors-for/c X y) = #f type-measure : (or/c 'deviance 'C) = 'deviance nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
A held-out fold’s own deviance is undefined when the fold has no event, or when its first event is among its last two observations in time order. R stops then, and so does cox-cv, naming the fold. With #:grouped? #t, the default, the fold’s own deviance is not needed.
> (define times (for/list ([v (in-list y60)]) (exp (* -0.3 v))))
> (define statuses (for/list ([i (in-range 60)]) (if (zero? (modulo i 5)) 0 1))) > (cox-cv X60 times statuses)
#<glmnet-cv:cox
Measure: Partial Likelihood Deviance
Lambda Index Measure SE Nonzero
min 0.02501 35 3.955 0.2004 7
1se 0.07637 23 4.137 0.1787 4>
> (cox-cv X60 times statuses #:type-measure 'C)
#<glmnet-cv:cox
Measure: C-index
Lambda Index Measure SE Nonzero
min 0.1764 14 0.95 0.01859 3
1se 0.1764 14 0.95 0.01859 3>
> (define survival60 (hash "time" times "status" statuses "x1" (map car X60) "x2" (map cadr X60))) > (cox-cv survival60 '("time" "status") #:predictors '("x1" "x2"))
#<glmnet-cv:cox
Measure: Partial Likelihood Deviance
Lambda Index Measure SE Nonzero
min 0.00986 45 4.789 0.3301 2
1se 0.16075 15 5.109 0.3501 2>
> (define thirds (for/list ([i (in-range 60)]) (modulo i 3)))
> (define fold-0-censored (for/list ([i (in-range 60)]) (if (zero? (modulo i 3)) 0 1))) > (cox-cv X60 times fold-0-censored #:fold-ids thirds #:grouped? #f) cox-cv: a held-out fold has no event, so its deviance is
undefined without grouping; use #:grouped? #t
held-out fold: 0
procedure
(poisson-cv X y [ #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c y : (response-for/c X (>=/c 0)) predictors : (predictors-for/c X y) = #f type-measure : (or/c 'deviance 'mse 'mae) = 'deviance nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define counts (for/list ([v (in-list y60)]) (inexact->exact (round (exp (* 0.3 v)))))) > (poisson-cv X60 counts)
#<glmnet-cv:poisson
Measure: Poisson Deviance
Lambda Index Measure SE Nonzero
min 0.02356 37 0.1920 0.03408 5
1se 0.09512 22 0.2242 0.04454 5>
> (poisson-cv (hash "count" counts "x1" (map car X60) "x2" (map cadr X60)) "count" #:predictors '("x1" "x2"))
#<glmnet-cv:poisson
Measure: Poisson Deviance
Lambda Index Measure SE Nonzero
min 0.00442 55 0.2375 0.05644 2
1se 0.15146 17 0.2868 0.07922 2>
procedure
(mgaussian-cv X Y [ #:predictors predictors #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → glmnet-cv? X : data/c Y : (responses-for/c X) predictors : (predictors-for/c X Y) = #f type-measure : (or/c 'mse 'deviance 'mae) = 'mse nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = #t thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define Y60 (for/list ([row (in-list X60)] [v (in-list y60)]) (list v (- (list-ref row 1) (list-ref row 3))))) > (mgaussian-cv X60 Y60)
#<glmnet-cv:mgaussian
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.03410 43 0.3820 0.03356 7
1se 0.09488 32 0.4129 0.03545 6>
> (mgaussian-cv mtcars '("mpg" "qsec") #:predictors '("wt" "hp") #:fold-ids (for/list ([i (in-range 32)]) (modulo i 4)))
#<glmnet-cv:mgaussian
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.1370 40 9.749 1.207 3
1se 0.8803 20 10.786 1.720 3>
procedure
(random-fold-ids n [#:nfolds nfolds])
→ (listof exact-nonnegative-integer?) n : exact-positive-integer? nfolds : exact-positive-integer? = 10
> (random-fold-ids 10 #:nfolds 3) '(0 0 2 2 0 0 1 2 1 1)
> (define (draw) (parameterize ([current-pseudo-random-generator (make-pseudo-random-generator)]) (random-seed 1) (random-fold-ids 10 #:nfolds 3))) > (equal? (draw) (draw)) #t
> (random-fold-ids 3 #:nfolds 5) random-fold-ids: contract violation;
there are more folds than observations
folds: 5
observations: 3
in: (->i
((n exact-positive-integer?))
(#:nfolds (nfolds exact-positive-integer?))
#:pre/desc
(n nfolds)
(folds-within n nfolds)
(_ (listof natural?)))
contract from: <pkgs>/glmnet/core/cv.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/cv.rkt:31:3
value
> (require racket/flonum) > (contract-first-order-passes? fold-ids/c '(0 1 2 0 1 2)) #t
> (contract-first-order-passes? fold-ids/c (flvector 0.0 1.0 2.0 2.0)) #t
> (contract-first-order-passes? fold-ids/c #f) #t
> (contract-first-order-passes? fold-ids/c '(0 1 0 1)) #f
> (contract-first-order-passes? fold-ids/c (vector 0 2 3 0 2 3)) #f
> (elnet-cv X60 y60 #:fold-ids (for/vector ([i (in-range 60)]) (modulo i 4)))
#<glmnet-cv:gaussian
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.04942 39 0.4160 0.04962 6
1se 0.13752 28 0.4639 0.11939 3>
> (elnet-cv X60 y60 #:fold-ids (for/list ([i (in-range 60)]) (* 2 (modulo i 3)))) elnet-cv: contract violation;
a fold has no observations; fold ids must cover 0 to 4
expected: an observation in fold 1
given: '(0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0
2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0 2 4 0
2 4 0 2 4)
in: the #:fold-ids argument of
(->*
(data/c (response-for/c X real?))
(#:predictors (predictors-for/c X y) ...)
glmnet-cv?)
contract from: <pkgs>/glmnet/core/elnet.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/elnet.rkt:86:3
2.16 Formulas
The formula front end fits any family from named data: a table (see Tables) or a Polars dataframe. A formula names the response and, in R’s formula algebra, the predictor terms. formula-fit, formula-path and formula-cv expand the terms against the data’s columns, as R’s terms does, build their design matrix, as R’s model.matrix does, and call the fit procedure, path fitter or cross-validation procedure of the family that #:family names on it. They return a formula-model, which keeps the formula, the names of the design matrix’s columns and the expanded terms, so that coef keys the coefficients by name and predict builds the design matrix of new named data (see Generic model interface). Formulas and named data works through examples, The formula algebra explains the algebra, Transforms the transforms, and Categorical predictors the factors.
A dataframe is read as (polars->table df) would be, and the results are the same, except that only the columns the formula uses are converted: those its terms read and, for a fit, the response columns. The other columns may have any dtype, and missing values. A converted column needs a numeric, boolean, string, categorical or enum dtype and no missing value; a response needs a numeric one, except the class labels of a binomial or multinomial response and a Cox status, which may be boolean. An error names the column. A dataframe with no rows is an error only for a formula that reads a column of it, as a table is.
The terms of a formula expand as R’s terms expands them:
A column name is a term of one variable, that column. all is a term for each column of the table that is not a response column, in the table’s order, as R’s . is.
A transform, such as (log hp) or (I (expt hp 2)), is a term of one variable, computed from columns (see below).
(factor x), R’s factor(x), is a term of one variable, the values of the column x or of the transform x as a factor (see below).
(+ a b), or a + b, is the terms of a, then those of b. Terms written side by side after the response are joined in the same way.
(- a b), or a - b, is the terms of a except those equal to a term of b. A term of b that a does not have is ignored. (- a) removes a from nothing.
(: a b), or a : b, is every term of a combined with every term of b: an interaction, whose variables are those of both.
(* a b), or a * b, crosses them: the terms of a + b + a : b. When a has no terms, as 1 and 0 have none, neither has a * b, as in R, whose y ~ 0*x + z is y ~ z - 1.
(^ a n), or a ^ n, crosses a with itself: every interaction of at most n of the terms of a, for an exact integer n of at least 2. A variable crossed with itself is itself, so (^ x 2) is x, as x^2 is in R.
1 keeps the intercept and 0 removes it, so - 1 removes it too. Inside the removed operand of - their meanings swap, and the last one written wins, as in R. A formula without them has an intercept.
A term is a set of variables, so (: wt hp) and (: hp wt) are the same term. Each operation drops the terms it repeats, keeping the first. The terms are then ordered by degree, the main effects first and then the interactions of two variables, of three, and so on, each degree in the order the terms first appear; the variables of a term are in the order they first appear in the formula. The prefix forms with more operands are the infix forms folded from the left: (* a b c) is a * b * c.
The design matrix, which formula-design-matrix returns, has one column per term for numeric variables: a column of the table, or for an interaction the product of its variables’ columns, named by joining their names with colons, as R names them: "wt:hp". A factor has a column for each of its levels, or for each but the first (see below), and an interaction a column for each combination of its variables’ columns, the first variable’s varying fastest. A column of the table keeps its name, where R puts backticks around a name that R’s syntax does not allow, such as "blood pressure". It has no intercept column, since the family’s procedure fits the intercept. Every column the formula names, even one that it removes, must be a column of the table, and so must the response columns, which must be distinct. Names are compared as strings. The design matrix’s column names must be distinct, and none can be "(Intercept)", since coef keys the coefficients by them and the intercept by "(Intercept)"; the formula procedures raise an error that names the column otherwise.
A group that starts with an identifier other than the operators, such as (log hp), is a transform, as R’s log(hp) is: a Racket expression, evaluated for each row of the table, whose values are a column of the design matrix named by the transform’s source, "(log hp)". (I expr), R’s I(), is the transform whose expression is expr. Inside a transform the operators are Racket’s: (I (* wt hp)) is the product of two columns, and (log (+ hp 1)) adds 1. An identifier in argument position, that is, not first in a group, is the table’s column of that name when the table has one, and otherwise the Racket binding of that name where the formula is written, as R looks for a name in the data and then in the formula’s environment. An identifier first in a group is always the Racket binding, even when the table has a column of that name, as R looks up the function of a call by name and skips a column: with a column max, (max max x) is the larger of that column and x, R’s pmax(max, x). A name that the transform binds itself, with let, lambda or a for form, is its own, a name in quoted data is data, and a name that Racket’s forms match as a literal, =>, else, unquote, unquote-splicing, ... or _, keeps its Racket meaning; the columns a transform reads are the others. A column named like one of these literals cannot be read inside a transform, where (log else) is Racket’s syntax error else: not allowed as an expression; write it as an ordinary term, or rename it in the table. The expression is evaluated once for each row, with each column name standing for the row’s value, so a transform is elementwise. A fit evaluates each transform the terms use once on the table, as R’s model.frame does, and takes a factor’s levels and the design matrix from those values, so a transform with side effects or random values gives both from the same draw. A transform that - removes is not evaluated, where R’s model.frame still evaluates it once. A column of numbers gives its value as a flonum, and a column of strings, symbols or booleans gives the value itself, as R’s calls read a character or logical column, so (equal? Species "setosa") is R’s I(Species == "setosa") and (not b) is R’s I(!b). A column that a transform reads must hold one kind of value, numbers, strings, symbols or booleans, and its numbers must be finite; an error names the transform and the column. Strings and symbols are two kinds here, though a factor’s levels match them by label, since a transform can tell them apart: (equal? g "a") is false for the symbol 'a. predict needs each such column to hold the kind of value it held when the model was fitted, and an error names the transform, the column and both kinds; a boolean column given as 1 and 0 would otherwise change (if b x 0) silently, as 0 is true in Racket. A name that is neither a column nor bound is an error, naming it, when the transform is evaluated, not when the formula is compiled. Each value must be a real number and finite, or else each a string, a symbol or a boolean, which makes the transform a factor (see below), and an error names the transform and the row. A transform must read at least one column. It is a variable of the algebra, so (* (log hp) wt) has the terms "(log hp)", "wt" and "(log hp):wt", and a transform written twice, as the same datum, is one term.
A variable is a factor, a categorical variable, when its values, a column’s or a transform’s, are strings or symbols, or booleans, as R’s character and logical variables are, and under (factor x), whose values may be numbers too. Otherwise its values must be numbers. A factor’s levels are its distinct values, labelled as R labels them: a string itself, a symbol’s name, "FALSE" and "TRUE" for booleans, and a number as Racket prints it, without a trailing .0; values with the same label are one level. They are sorted as R’s factor() sorts them: numbers by value, labels by string<?, which is R’s order in the C locale, and "FALSE" before "TRUE". A boolean variable other than (factor x) has both boolean levels, even when one is absent, as R’s logical variable has. A factor needs at least two levels; a column or a transform whose values mix numbers, strings or symbols, and booleans is an error that names it. A factor is coded by treatment contrasts, as R’s model.matrix codes it by default: a 0/1 column for each level but the first, the baseline, named by the variable’s name and the level’s label, as "(factor cyl)6" or "Speciesversicolor". It has a column for every level instead, dummies, where R’s model.matrix has: in a term that has other variables, when no earlier term contains all of them (R’s factors attribute of terms), and, without an intercept, for the first factor of the first term that has one. So in (~ mpg wt : (factor cyl)) the factor has dummies, and after wt, or after wt : hp, which contains wt, it has contrasts. The fitted model keeps the levels (see formula-model-levels), and predict codes a new table with them; a value whose level the model was not fitted with is an error that names the factor and the new levels.
A response column that stands alone as a term on the right-hand side is dropped from it, and a warning naming the procedure called is logged on the 'glmnet topic, as R’s model.matrix warns. An interaction with a response column is kept, as in R. The columns of a (surv time status) or multi-column response are each treated in the same way.
The intercept of the fit is the formula’s: without #:intercept?, the fit procedures fit an intercept unless the formula has 0 or - 1. An explicit #:intercept? must agree with a formula that writes 1, 0 or - 1, which its contract checks, naming both; with a formula that writes none, it decides. The Cox family fits no intercept, and accepts 1, 0 and - 1 with any #:intercept?. As in R, they still decide how a factor is coded: with 0 or - 1, the first factor has a column for every level (see above). A formula whose terms leave no predictors, such as (~ y 1), cannot be fitted: glmnet needs at least one predictor.
The examples in this section use R’s mtcars, 32 cars of the 1974 Motor Trend road tests, and R’s iris, 150 irises of three species, which glmnet/datasets provides as tables (see Example datasets):
> (require glmnet/data/polars glmnet/datasets) > (table-column-names mtcars) '("mpg" "cyl" "disp" "hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
> (table-column-names iris) '("Sepal.Length" "Sepal.Width" "Petal.Length" "Petal.Width" "Species")
Some also use mtcars as a dataframe, from the datasets package, with a text column of the cars’ names:
> (require (only-in datasets load-dataset) (only-in polars column-names) (prefix-in pl: (only-in polars head))) > (define cars (load-dataset 'mtcars #:format 'polars)) > (column-names cars) '("model" "mpg" "cyl" "disp" "hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
syntax
(~ response term ...)
(~ response maybe-sign term operation ...)
response = column | (surv time-column status-column) | (column ...+) term = column | all | 1 | 0 | (+ term ...+) | (- term ...+) | (* term term ...+) | (: term term ...+) | (^ term power) | (maybe-sign term operation ...+) | (I expr) | (proc-id arg-expr ...) | (factor column) | (factor (I expr)) | (factor (proc-id arg-expr ...)) operation = + term | - term | * term | : term | ^ power maybe-sign =
| + | - column = identifier | string
The body is quoted, as by quote, except for its transforms, and the result is (make-formula 'response rhs ...), with the elements of the right-hand side as written. Each transform becomes a transform-term? value that computes it, whose name is its source, the datum as write writes it with print-reader-abbreviations on, so that quoted data is written 'x and not (quote x). A transform’s proc-id must be bound where the formula is written: in a module, anywhere in it; at the top level, as in the REPL, by a definition evaluated before the formula, since a later one cannot be seen there. A name in argument position is read when the transform runs, so at the top level it can be defined after the formula. An arg-expr or the expr of I is any Racket expression, checked as it is expanded, where the names bound in it are known: ^, R’s power, is a syntax error that says to write expt unless it is bound, and so is R’s infix arithmetic, such as (hp * wt), whose first name is not bound, which says to write (* hp wt). A column is written as an identifier or a string, and as a string when its name is a word of the formula language (all, surv, the operators, and R’s / and %in%, which it does not have), starts with -, or contains :, *, ^, / or +. The reader reads wt:hp and -wt as one name, so an operator needs spaces around it; written as an identifier, such a name is a syntax error that says so. So is a number other than 0 and 1; a 0 or 1 written with more than its digit, such as -0 or +0, since the reader reads both as 0 and drops the sign that R reads as an operator, so that R’s -0 is written (- 0) and its +0 (+ 0); a group that is neither a prefix form, an infix form nor a transform, such as (1 x z); a quoted name, such as 'hp, since ~ quotes the names itself; and R’s / or %in%, between terms or at the head of a group, where the error for / says to write a ratio as (I (/ hp wt)). The error points at the form that is wrong. Inside a transform, a column whose name is not an identifier is written with bars, as (log |blood pressure|).
Whether a 0 or 1 is written with more than its digit is read from its source location, the only trace of its spelling. A macro that builds one into a formula therefore gives it a location of its own, or none: a 0 made by datum->syntax with the location of a longer form, such as the #f option it stands for, counts as written with more than its digit, and is a syntax error.
(factor column) is R’s factor(column), and is quoted as the list (factor column). factor of a transform is the list of 'factor and the transform’s transform-term? value. A factor group takes one column or transform, and is named by its source, as "(factor cyl)"; a column whose name is not an identifier is written there as a string, "(factor \"n k\")".
The response is one column, (surv time-column status-column) for the Cox family, or a list of columns for the multi-response Gaussian family. It is not a transform: a response that starts with I, or with a bound name and holds more than column names, such as (log (+ mpg 1)), is a syntax error that says a transformed response is not supported. So is a list of columns whose first name is a procedure where the formula is written, such as (log mpg), an error raised when the formula is made, as only then is the value known; the columns of such a response are written as strings, as in ("log" "mpg").
> (~ mpg (* wt hp)) (~ mpg (* wt hp))
> (mpg . ~ . wt * hp) (~ mpg wt * hp)
> (formula-predictor-names (mpg . ~ . wt * hp) mtcars) '("wt" "hp" "wt:hp")
> (formula-predictor-names (~ mpg (^ (+ wt hp qsec) 2)) mtcars) '("wt" "hp" "qsec" "wt:hp" "wt:qsec" "hp:qsec")
> (formula-predictor-names (mpg . ~ . (wt + hp + qsec) ^ 2 - wt : hp) mtcars) '("wt" "hp" "qsec" "wt:qsec" "hp:qsec")
> (formula-predictor-names (mpg . ~ . 0 + wt + hp) mtcars) '("wt" "hp")
> (formula-predictor-names (~ mpg (- all cyl disp)) mtcars) '("hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
> (formula-predictor-names (mpg . ~ . (log hp) * wt + (I (/ disp cyl))) mtcars) '("(log hp)" "wt" "(I (/ disp cyl))" "(log hp):wt")
> (formula-predictor-names (mpg . ~ . wt * (factor cyl)) mtcars) '("wt" "(factor cyl)6" "(factor cyl)8" "wt:(factor cyl)6" "wt:(factor cyl)8")
> (formula-predictor-names (mpg . ~ . (factor (> gear 3)) + wt) mtcars) '("(factor (> gear 3))TRUE" "wt")
> (formula-predictor-names (Sepal.Length . ~ . 0 + Species + Petal.Width) iris) '("Speciessetosa" "Speciesversicolor" "Speciesvirginica" "Petal.Width")
> (formula-predictor-names (Sepal.Length . ~ . (equal? Species "setosa") + Petal.Width) iris) '("(equal? Species \"setosa\")TRUE" "Petal.Width")
> (~ (surv time status) age "blood pressure") (~ (surv time status) age "blood pressure")
> (~ mpg wt:hp) eval:347:0: ~: wt:hp reads as one name; put spaces around an
operator, as in wt : hp, or write a column with this name as
a string, "wt:hp"
at: wt:hp
in: (~ mpg wt:hp)
parsing context:
while parsing a column name
term: wt:hp
location: eval:347:0
while parsing a term: a column, all, 1, 0, a transform
such as (log x), (factor x), or a group such as (* x z) or
(x + z)
term: wt:hp
location: eval:347:0
while parsing the right-hand side of a formula
term: (wt:hp)
location: eval:347:0
value
> (formula-term/c '(* wt hp)) #t
> (formula-term/c '(wt + hp)) #t
> (formula-term/c '(^ (+ wt hp) 2)) #t
> (formula-term/c (transform-term "(log wt)" '(wt) log)) #t
> (formula-term/c '(factor cyl)) #t
> (formula-term/c '(log wt)) #f
value
> (formula-rhs/c '(wt hp (: wt hp))) #t
> (formula-rhs/c '(- 1 + wt * hp)) #t
> (formula-rhs/c '(wt hp + qsec)) #f
value
> (formula-response/c '(surv time status)) #t
> (formula-response/c '(surv time)) #f
procedure
(transform-term name columns proc) → transform-term?
name : string? columns : (and/c (listof (or/c string? symbol?)) pair?) proc : (procedure-arity-includes/c (length columns))
A procedure has no source and names no columns, so a transform as data names both. Two transforms are equal? when their names and columns are, so a transform named by its source is equal? to the one that ~ makes from that source. It prints as #<transform-term and its name, and a formula prints it as its name.
> (define log-hp (transform-term "(log hp)" '(hp) log)) > (define f (make-formula 'mpg log-hp '* 'wt)) > f (~ mpg (log hp) * wt)
> (equal? f (mpg . ~ . (log hp) * wt)) #t
> (define power-to-weight (transform-term "hp/wt" '("hp" "wt") /)) > (define P (formula-design-matrix (make-formula 'mpg power-to-weight) mtcars)) > (design-matrix->rows (design-matrix-select-rows P '(0 1 2))) '((41.98473282442748) (38.26086956521739) (40.08620689655173))
procedure
(transform-term? v) → boolean?
v : any/c
> (formula-terms (~ mpg (log hp) wt)) '(#<transform-term (log hp)> wt)
> (transform-term? (car (formula-terms (~ mpg (log hp) wt)))) #t
procedure
(make-formula response rhs ...) → formula?
response : formula-response/c rhs : any/c
> (define chosen '("wt" "hp" "qsec")) > (apply make-formula "mpg" chosen) (~ "mpg" "wt" "hp" "qsec")
> (make-formula 'mpg `(^ (+ ,@chosen) 2)) (~ mpg (^ (+ "wt" "hp" "qsec") 2))
> (make-formula 'mpg 'wt '* 'hp) (~ mpg wt * hp)
> (equal? (make-formula 'mpg 'wt '* 'hp) (mpg . ~ . wt * hp)) #t
> (make-formula 'mpg 'wt (list 'factor "cyl")) (~ mpg wt (factor "cyl"))
> (formula? (~ mpg all)) #t
> (formula? '(~ mpg all)) #f
> (equal? (~ mpg wt * hp) (mpg . ~ . wt * hp)) #t
procedure
f : formula?
procedure
(formula-terms f) → formula-rhs/c
f : formula?
> (formula-response (~ (surv time status) age)) '(surv time status)
> (formula-terms (mpg . ~ . 1 + wt * hp)) '(1 + wt * hp)
> (formula-terms (~ mpg wt (- all cyl))) '(wt (- all cyl))
procedure
(formula-predictor-names f data) → (listof string?)
f : formula? data : (or/c table? named-data?)
> (formula-predictor-names (~ mpg wt hp (: wt hp qsec)) mtcars) '("wt" "hp" "wt:hp:qsec")
> (formula-predictor-names (mpg . ~ . wt * hp * qsec - wt : hp : qsec) mtcars) '("wt" "hp" "qsec" "wt:hp" "wt:qsec" "hp:qsec")
> (formula-predictor-names (~ mpg (: all wt)) mtcars)
'("wt"
"cyl:wt"
"disp:wt"
"hp:wt"
"drat:wt"
"wt:qsec"
"wt:vs"
"wt:am"
"wt:gear"
"wt:carb")
> (formula-predictor-names (mpg . ~ . (factor cyl) * (factor am)) mtcars)
'("(factor cyl)6"
"(factor cyl)8"
"(factor am)1"
"(factor cyl)6:(factor am)1"
"(factor cyl)8:(factor am)1")
> (formula-predictor-names (~ mpg 1) mtcars) '()
> (formula-predictor-names (~ mpg (- all model)) cars) '("cyl" "disp" "hp" "drat" "wt" "qsec" "vs" "am" "gear" "carb")
procedure
(formula-design-matrix f data) → design-matrix?
f : formula? data : (or/c table? named-data?)
> (define X (formula-design-matrix (~ mpg (* wt hp)) mtcars)) > X #<design-matrix 32x3>
> (design-matrix-column-names X) '("wt" "hp" "wt:hp")
> (design-matrix->rows (design-matrix-select-rows X '(0 1 2))) '((2.62 110.0 288.2) (2.875 110.0 316.25) (2.32 93.0 215.76))
> (define L (formula-design-matrix (~ mpg hp (log hp) (I (expt hp 2))) mtcars)) > (design-matrix->rows (design-matrix-select-rows L '(0 1 2)))
'((110.0 4.700480365792417 12100.0)
(110.0 4.700480365792417 12100.0)
(93.0 4.532599493153256 8649.0))
> (define F (formula-design-matrix (~ mpg wt (factor cyl)) mtcars)) > (design-matrix-column-names F) '("wt" "(factor cyl)6" "(factor cyl)8")
> (design-matrix->rows (design-matrix-select-rows F '(0 1 2))) '((2.62 1.0 0.0) (2.875 1.0 0.0) (2.32 0.0 0.0))
struct
(struct formula-model (formula predictor-names fit) #:transparent) formula : formula? predictor-names : (listof string?) fit : glmnet-model?
A formula model implements gen:glmnet-model through fit: predict, coef and deviance-ratio give what they give for fit, except that coef keys the coefficients by name and predict takes a table or a dataframe, from whose columns it builds the design matrix of the fitted terms, reading only those the terms read. It does not expand the formula again, so all stands for the columns it stood for in the fit, and the new data’s columns can come in any order, without the response. It evaluates the transforms again, on the new rows: each name of a transform that was a column in the fit must be a column of the new data, and one that was a Racket binding is read again. It codes the factors with the fit’s levels, whichever of them the new rows have, and a level that the fit did not have is an error that names the factor and the new levels. For a response with classes, coef keys a multinomial model’s coefficients by class, and predict with #:type 'class returns classes, as R’s glmnet does for a factor response. glmnet-model-predictor-names returns predictor-names, and glmnet-model-response-names the formula’s response columns. A formula model prints as fit does, with the formula after the family.
> (define m (formula-fit (mpg . ~ . wt * hp) mtcars #:lambda 0.1)) > m #<glmnet:gaussian (~ mpg wt * hp) λ=0.1 dev=0.8321 nz=3/3>
> (formula-model-predictor-names m) '("wt" "hp" "wt:hp")
> (formula-model-fit m) #<glmnet:gaussian λ=0.1 dev=0.8321 nz=3/3>
> (predict m (list (cons "hp" '(100 200)) (cons "wt" '(2.5 3.5)))) '(24.262928395522646 17.32517427651279)
> (define logged (formula-fit (mpg . ~ . (log hp) + wt) mtcars #:lambda 0.1)) > (predict logged (list (cons "hp" '(100 200)) (cons "wt" '(2.5 3.5)))) '(24.008240583293016 16.76430275840009)
> (define by-cylinders (formula-fit (mpg . ~ . wt + (factor cyl)) mtcars #:lambda 0.1)) > (predict by-cylinders (list (cons "cyl" '(8 4)) (cons "wt" '(3.5 2.5)))) '(16.846901087575166 25.69733799740451)
> (formula-model-levels (formula-fit (mpg . ~ . wt + (factor cyl)) mtcars #:lambda 0.1)) '(("(factor cyl)" "4" "6" "8"))
> (formula-model-levels (formula-fit (Sepal.Length . ~ . Species * Petal.Width + (> Sepal.Width 3)) iris #:lambda 0.01))
'(("Species" "setosa" "versicolor" "virginica")
("(> Sepal.Width 3)" "FALSE" "TRUE"))
> (formula-model-levels (formula-fit (mpg . ~ . wt + hp) mtcars #:lambda 0.1)) '()
procedure
(formula-fit f data #:lambda lambda [ #:family family #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → formula-model? f : formula? data : (or/c table? named-data?) lambda : (>=/c 0)
family : (or/c 'gaussian 'binomial 'multinomial 'poisson 'cox 'mgaussian) = 'gaussian alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = the formula’s thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
The response of f must suit family, which the contract on f checks: (surv time status) for the Cox family, one or more columns for the multi-response family, and one column otherwise. Its values must be ones the family models: 0 or 1 for the binomial family, class labels 0, 1, …, K−1 with K ≥ 2 and every class present for the multinomial family, non-negative for the Poisson family, and for the Cox family positive times and 0/1 statuses. An error names the column, and either the row of a value the family does not model or the missing class label. A binomial or multinomial response may instead hold strings, symbols or booleans, whose levels, sorted as a factor’s are, are its classes, as R’s glmnet makes a factor response’s: two for the binomial family, whose second is the class the model gives the probability of, and at least two for the multinomial family. An error that the family’s procedure raises names formula-fit.
> (define fit (formula-fit (mpg . ~ . wt * hp) mtcars #:lambda 0.1)) > (coef fit)
'(("(Intercept)" . 37.528269700740594)
("wt" . -4.032185075172319)
("hp" . -0.03534015584099164)
("wt:hp" . 0.0013965478672480604))
> (coef (formula-fit (mpg . ~ . 0 + wt * hp) mtcars #:lambda 0.1))
'(("(Intercept)" . 0.0)
("wt" . 8.54890203027654)
("hp" . 0.1709322727567094)
("wt:hp" . -0.06445423956453895))
> (coef (formula-fit (mpg . ~ . hp + (I (expt hp 2))) mtcars #:lambda 0.1))
'(("(Intercept)" . 36.37284540325939)
("hp" . -0.15811445359642218)
("(I (expt hp 2))" . 0.00026508932547340944))
> (coef (formula-fit (mpg . ~ . wt + (factor cyl)) mtcars #:lambda 0.1))
'(("(Intercept)" . 33.87775166152442)
("wt" . -3.2721654656479635)
("(factor cyl)6" . -3.7451819901218832)
("(factor cyl)8" . -5.578271444181383))
> (formula-fit (am . ~ . wt + hp) mtcars #:family 'binomial #:lambda 0.05) #<glmnet:binomial (~ am wt + hp) λ=0.05 dev=0.5891 nz=2/2>
> (map car (coef (formula-fit (~ Species all) iris #:family 'multinomial #:lambda 0.05))) '("setosa" "versicolor" "virginica")
> (define car-model (formula-fit (~ mpg (+ wt hp)) cars #:lambda 0)) > (coef car-model)
'(("(Intercept)" . 37.227908544960556)
("wt" . -3.878178045360442)
("hp" . -0.03176968200102037))
> (predict car-model (pl:head cars 3)) '(23.57241704600396 22.583481644437047 25.27595505362944)
> (formula-fit (~ mpg 1) mtcars #:lambda 0.1) formula-fit: the formula has no predictors, and glmnet needs
at least one
formula: (~ mpg 1)
> (formula-fit (~ model wt) cars #:lambda 0.1) formula-fit: the response column "model" is not numeric
dtype: 'string
procedure
(formula-path f data [ #:family family #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → formula-model? f : formula? data : (or/c table? named-data?)
family : (or/c 'gaussian 'binomial 'multinomial 'poisson 'cox 'mgaussian) = 'gaussian lambda : (or/c #f (and/c (listof (>=/c 0)) pair?)) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = the formula’s thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define path (formula-path (~ mpg (^ (+ wt hp qsec) 2)) mtcars #:lambda '(1.0 0.5 0.1))) > path
#<glmnet-path:gaussian (~ mpg (^ (+ wt hp qsec) 2))
Df %Dev Lambda
1 2 79.13 1.0
2 3 82.40 0.5
3 5 84.72 0.1>
> (coef path #:lambda 0.1)
'(("(Intercept)" . 26.53010769463421)
("wt" . -3.8107083219778004)
("hp" . 0.0)
("qsec" . 0.616278426076173)
("wt:hp" . 0.0023632916212049395)
("wt:qsec" . -0.023873512814479348)
("hp:qsec" . -0.001985660316630189))
> (formula-path (~ am (- all model)) cars #:family 'binomial #:nlambda 5)
#<glmnet-path:binomial (~ am (- all model))
Df %Dev Lambda
1 0 0.00 0.39000
2 3 81.89 0.03900
3 4 97.37 0.00390
4 6 99.72 0.00039
5 6 99.97 0.00004>
procedure
(formula-cv f data [ #:family family #:type-measure type-measure #:nfolds nfolds #:fold-ids fold-ids #:grouped? grouped? #:lambda lambda #:nlambda nlambda #:lambda-min-ratio lambda-min-ratio #:alpha alpha #:standardize? standardize? #:intercept? intercept? #:thresh thresh #:max-iters max-iters]) → formula-model? f : formula? data : (or/c table? named-data?)
family : (or/c 'gaussian 'binomial 'multinomial 'poisson 'cox 'mgaussian) = 'gaussian
type-measure : (or/c #f 'mse 'deviance 'mae 'class 'auc 'C) = #f nfolds : (and/c exact-integer? (>=/c 3)) = 10 fold-ids : fold-ids/c = #f grouped? : boolean? = #t
lambda : (or/c #f (and/c (listof (>=/c 0)) (property/c length (>=/c 2)))) = #f nlambda : exact-positive-integer? = 100
lambda-min-ratio : (or/c #f (and/c real? (>=/c 0) (</c 1))) = #f alpha : (real-in 0 1) = 1.0 standardize? : boolean? = #t intercept? : boolean? = the formula’s thresh : (>/c 0) = 1e-7 max-iters : exact-positive-integer? = 100000
> (define folds (for/list ([i (in-range 32)]) (modulo i 4))) > (define cv-model (formula-cv (mpg . ~ . wt * hp) mtcars #:fold-ids folds)) > cv-model
#<glmnet-cv:gaussian (~ mpg wt * hp)
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.00250 83 6.08 0.6064 3
1se 0.04477 52 6.61 0.6951 3>
> (coef cv-model)
'(("(Intercept)" . 44.18599782499345)
("wt" . -6.301381407673056)
("hp" . -0.08130232129662496)
("wt:hp" . 0.015743383605847892))
> (define iris-df (table->polars iris))
> (define flowers (formula-cv (~ Species all) iris-df #:family 'multinomial #:fold-ids (for/list ([i (in-range 150)]) (modulo i 5)))) > (predict flowers (pl:head iris-df 3) #:type 'class #:lambda 'lambda-1se) '("setosa" "setosa" "setosa")
2.17 Generic model interface
Every result type implements one generic interface, gen:glmnet-model: the six single-λ results (elnet-result, logistic-result, multinomial-result, cox-result, poisson-result and mgaussian-result), glmnet-path, glmnet-cv and formula-model. predict, coef and deviance-ratio follow R’s predict, coef and dev.ratio for glmnet and cv.glmnet fits. See Predictions and coefficients.
The interface reads every model as a regularization path: a single-λ fit is a path with one λ. Where #:lambda names a λ that is not on the path, predict and coef follow R’s rule (its exact = FALSE, the default):
Between two fitted values λl > s > λr, the intercepts and coefficients are interpolated linearly in λ: β(s) = w β(λl) + (1 − w) β(λr), with w = (s − λr) / (λl − λr).
Above the largest fitted λ, or below the smallest, s is clamped to that end of the path.
A model with one λ, such as a single fit, gives that fit for every s.
A cross-validated model also names two λ values, 'lambda-min and 'lambda-1se, which #:lambda accepts in place of a number, as R’s s accepts "lambda.min" and "lambda.1se".
A model can also name its predictors, as a formula-model does. Then coef keys its coefficients by name, as R’s coef names its rows, and predict takes a table or a dataframe and reads the predictors from it by name, or, for a formula model, builds them from its columns, as its formula’s terms say.
predict, coef and glmnet-model-default-lambda need a model with at least one fitted λ. A glmnet-path built by hand can have none, and they reject such a model with a contract error that blames the caller.
The examples in this section use a single fit and a path of the Gaussian family:
> (require glmnet/data/polars glmnet/datasets)
> (define X '((1.0 2.0 1.0) (2.0 1.0 4.0) (3.0 4.0 9.0) (4.0 3.0 16.0) (5.0 6.0 25.0) (6.0 5.0 36.0))) > (define y '(1.0 4.0 3.0 6.0 5.0 8.0)) > (define fit (lasso X y #:lambda 0.05)) > (define path (elnet-path X y #:lambda '(1.0 0.1 0.01)))
syntax
glmnet-model->path, which must be implemented;
glmnet-model-default-lambda, which defaults to the first λ of the model’s path;
glmnet-model-named-lambda, which defaults to naming no λ;
glmnet-model-predictor-names and glmnet-model-response-names, which default to naming no predictors and no responses;
deviance-ratio, which defaults to the first deviance ratio of the model’s path.
The defaults suit a single fit. glmnet-path and glmnet-cv implement the ones that differ for them, and formula-model implements all six. A new type, such as a path together with a chosen λ, implements the interface through the #:methods option of struct, and then works with predict and coef:
> (require racket/generic)
> (struct chosen (path index) #:methods gen:glmnet-model [(define (glmnet-model->path m) (chosen-path m)) (define (glmnet-model-default-lambda m) (vector-ref (glmnet-path-lambda (chosen-path m)) (chosen-index m))) (define (deviance-ratio m) (vector-ref (glmnet-path-dev-ratio (chosen-path m)) (chosen-index m)))]) > (define best (chosen path 1)) > (coef best) '#(1.0000000000001843 1.6584349744677054 -0.6584349744677581 0.0)
> (deviance-ratio best) 0.9762711864406388
procedure
(glmnet-model? v) → boolean?
v : any/c
> (glmnet-model? fit) #t
> (glmnet-model? path) #t
> (glmnet-model? X) #f
procedure
(glmnet-model->path model) → glmnet-path?
model : glmnet-model?
> (glmnet-model->path fit)
#<glmnet-path:gaussian
Df %Dev Lambda
1 2 99.41 0.05>
> (glmnet-path-coefficients (glmnet-model->path fit)) '#(#(1.8292174872340037 -0.8292174872340038 0.0))
procedure
(glmnet-model-default-lambda model)
→ (or/c (>=/c 0) (and/c (listof (>=/c 0)) pair?)) model : glmnet-model?
> (glmnet-model-default-lambda fit) 0.05
> (glmnet-model-default-lambda path) '(1.0 0.1 0.01)
procedure
(glmnet-model-named-lambda model name) → (or/c #f (>=/c 0))
model : glmnet-model? name : (or/c 'lambda-min 'lambda-1se)
> (glmnet-model-named-lambda path 'lambda-min) #f
> (coef path #:lambda 'lambda-min) coef: only a cross-validated model has a named lambda
lambda: 'lambda-min
procedure
(glmnet-model-predictor-names model)
→ (or/c #f (listof string?)) model : glmnet-model?
> (define named-model (formula-fit (~ y all) (list (cons "y" y) (cons "a" (map car X)) (cons "b" (map cadr X)) (cons "c" (map caddr X))) #:lambda 0.05)) > (glmnet-model-predictor-names named-model) '("a" "b" "c")
> (glmnet-model-predictor-names car-fit) '("wt" "hp")
> (glmnet-model-predictor-names fit) #f
procedure
(glmnet-model-response-names model)
→ (or/c #f (listof string?)) model : glmnet-model?
> (glmnet-model-response-names named-model) '("y")
> (glmnet-model-response-names path) #f
procedure
(glmnet-model-class-labels model) → (or/c #f (listof string?))
model : glmnet-model?
> (glmnet-model-class-labels flowers) '("setosa" "versicolor" "virginica")
> (glmnet-model-class-labels (multinomial-fit X '(0 1 2 0 1 2) #:lambda 0.05)) #f
procedure
(deviance-ratio model) → (or/c real? (vectorof real?))
model : glmnet-model?
> (deviance-ratio fit) 0.9940677966101694
> (deviance-ratio path) '#(0.6106537530266343 0.9762711864406388 0.9997591646825783)
procedure
model : glmnet-model? X : data/c type : (or/c 'link 'response 'class) = 'link
lambda :
(or/c (>=/c 0) (and/c (listof (>=/c 0)) pair?) 'lambda-min 'lambda-1se) = (glmnet-model-default-lambda model)
Family |
| 'link |
| 'response |
| 'class |
Gaussian, multi-response |
| η = β₀ + xβ |
| η |
| --- |
Binomial |
| log-odds η |
| P(y = 1) |
| 1 if η > 0, else 0 |
Multinomial |
| ηk, one per class |
| softmax of the ηk |
| the class with the largest ηk |
Cox |
| xβ |
| exp(xβ) |
| --- |
Poisson |
| log μ = η |
| μ = exp(η) |
| --- |
'class is an error for the families without classes. A class is its label, 0, 1, …, except for a formula-model or a fit whose response holds strings, symbols or booleans, whose classes are the labels of its levels, such as "setosa" (see formula-fit and Data arguments). For one λ, the result has one entry per row of X: a real, a class, or, for the multinomial and multi-response families, a list with one entry per class or response. When lambda is a list, the result is a list of those, one per element of lambda, in the same order. 'lambda-min and 'lambda-1se stand for the λ values a glmnet-cv chose (see glmnet-model-named-lambda).
> (predict fit '((7.0 6.0 49.0) (0.0 0.0 0.0))) '(8.829217487234002 0.9999999999999996)
> (predict path '((7.0 6.0 49.0)) #:lambda 0.5) '(7.72162380661891)
> (predict path '((7.0 6.0 49.0)) #:lambda '(2.0 0.5 0.01)) '((6.550609846808079) (7.72162380661891) (8.972181135456438))
> (define clf (logistic-fit X '(0 0 0 1 1 1) #:lambda 0.05)) > (predict clf '((2.0 3.0 4.0) (5.0 4.0 25.0))) '(-2.7629680455517835 2.7629680455517853)
> (predict clf '((2.0 3.0 4.0) (5.0 4.0 25.0)) #:type 'response) '(0.05935842823867659 0.9406415717613236)
> (predict clf '((2.0 3.0 4.0) (5.0 4.0 25.0)) #:type 'class) '(0 1)
> (predict fit X #:type 'class) predict: type 'class is only for the binomial and
multinomial families
family: 'gaussian
> (define new-table (list (cons "c" '(49.0)) (cons "b" '(6.0)) (cons "a" '(7.0)))) > (predict named-model new-table) '(8.829217487234002)
> (predict named-model (table->polars new-table)) '(8.829217487234002)
> (predict named-model (cdr new-table)) predict: the table has no column with this name
column: "c"
columns of the table: '("b" "a")
procedure
model : glmnet-model?
lambda :
(or/c (>=/c 0) (and/c (listof (>=/c 0)) pair?) 'lambda-min 'lambda-1se) = (glmnet-model-default-lambda model)
For a model that names its predictors, each vector is an association list instead, keyed as R’s coef names its rows: "(Intercept)" (not for Cox), then the predictor names. For the multinomial family, the association lists are in turn keyed by class, as predict labels the classes, and for the multi-response family by response name (see glmnet-model-response-names; "y1", "y2", … when the model names no responses), as R names the elements of its lists.
> (coef fit) '#(0.9999999999999996 1.8292174872340037 -0.8292174872340038 0.0)
> (coef path #:lambda 0.1) '#(1.0000000000001843 1.6584349744677054 -0.6584349744677581 0.0)
> (coef path #:lambda 0.4) '#(1.483130051064096 1.3009194921982872 -0.43895664964517206 0.0)
> (coef path #:lambda 5.0) '#(2.449390153191919 0.5858885276594514 0.0 0.0)
> (coef named-model)
'(("(Intercept)" . 0.9999999999999996)
("a" . 1.8292174872340037)
("b" . -0.8292174872340038)
("c" . 0.0))
> (coef (glmnet-path 'gaussian (vector) (vector) (vector) (vector) (vector) 0)) coef: contract violation;
the model has at least one fitted λ
model: #<glmnet-path:gaussian
Df %Dev Lambda>
in: (->i
((model glmnet-model?))
(#:lambda
(s
(or/c
(or/c
(>=/c 0)
(non-empty-listof (>=/c 0)))
(or/c 'lambda-min 'lambda-1se))))
#:pre/name
(model)
"the model has at least one fitted λ"
(fitted? model)
(result (or/c vector? (listof any/c))))
contract from: <pkgs>/glmnet/core/model.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/core/model.rkt:81:3
procedure
model : glmnet-model?
> (for ([(λ β) (in-path path)]) (printf "~a: ~a\n" λ β))
1.0: #(2.449390153191919 0.5858885276594514 0.0 0.0)
0.1: #(1.0000000000001843 1.6584349744677054 -0.6584349744677581 0.0)
0.01: #(1.0089698059122343 1.9597271819899955 -0.9658434974467867 0.0008200416386725593)
> (for/list ([(λ β) (in-path (formula-path (~ mpg (+ wt hp)) mtcars #:nlambda 4))]) β)
'((("(Intercept)" . 20.090624999999996) ("wt" . 0.0) ("hp" . 0.0))
(("(Intercept)" . 36.43365390533786)
("wt" . -3.7286031193229756)
("hp" . -0.029635657569295454))
(("(Intercept)" . 37.19156099616917)
("wt" . -3.871517446859316)
("hp" . -0.0316679777776637))
(("(Intercept)" . 37.22625501504155)
("wt" . -3.8778871518235714)
("hp" . -0.03176478960945665)))
2.17.1 Printing
A single fit prints on one line with its family, its λ (to four significant digits), its deviance ratio (to four decimal places) and the number of nonzero coefficients out of the number of predictors, counting a predictor once when it is nonzero for any class or response.
A path prints R’s print.glmnet table line for line, without the Call: line R prints above it. Each fitted λ has a row, numbered from 1, with Df, the deviance ratio as a percentage rounded to two places (%Dev), and λ to four significant digits (Lambda). As in R, %Dev and Lambda are then rounded to about five significant digits of the column’s largest value, so a λ far below the first can show as 0, and each column is written with one number of decimals throughout, or in scientific notation when that is narrower.
A glmnet-cv prints as R’s print.cv.glmnet, without its Call: line and blank lines, under a #<glmnet-cv:family header. A formula-model prints as the result it holds, with its formula after the family.
Printing does not change equal?, which compares results field by field.
> (list fit clf)
'(#<glmnet:gaussian λ=0.05 dev=0.9941 nz=2/3>
#<glmnet:binomial λ=0.05 dev=0.8046 nz=1/3>)
> (define Xm '((1.0 1.0) (2.0 1.0) (5.0 1.0) (6.0 1.0) (3.0 5.0) (4.0 6.0))) > (multinomial-fit Xm '(0 0 1 1 2 2) #:lambda 0.05) #<glmnet:multinomial λ=0.05 dev=0.9150 nz=2/2>
> (multinomial-path Xm '(0 0 1 1 2 2) #:nlambda 4)
#<glmnet-path:multinomial
Df %Dev Lambda
1 0 0.00 0.46710
2 2 96.30 0.02168
3 2 99.82 0.00101
4 2 99.99 0.00005>
> cv
#<glmnet-cv:gaussian
Measure: Mean-Squared Error
Lambda Index Measure SE Nonzero
min 0.05424 38 0.3984 0.05967 6
1se 0.16564 26 0.4468 0.06523 3>
> named-model #<glmnet:gaussian (~ y all) λ=0.05 dev=0.9941 nz=2/3>
> (equal? fit (lasso X y #:lambda 0.05)) #t
2.18 Native library
These call straight into libglmnetcompat. Loading glmnet checks both and raises exn:fail if either is wrong. See The native library.
procedure
procedure
2.19 Plots
| (require glmnet/plot) | package: glmnet |
glmnet/plot draws a glmnet-path and a glmnet-cv, or a formula-model that holds one, as R’s plot draws a glmnet and a cv.glmnet fit. The guide’s Plots chapter shows every plot and how to read it. glmnet does not re-export these bindings, so that (require glmnet) does not load the plot library. Each plot is a pict?, drawn with plot/no-gui, whose parameters apply to it, and each plot procedure has a companion that returns the plot’s renderers, without the axes, to combine with other plot-lib renderers.
The examples in this section plot the lasso path of the fixture of Gaussian models, a multinomial path of three separable classes, the cross-validated fit cv of Cross-validation, and the formula model cv-model of formula-cv:
> (require glmnet/datasets glmnet/plot)
> (define X '((1.0 2.0 1.0) (2.0 1.0 4.0) (3.0 4.0 9.0) (4.0 3.0 16.0) (5.0 6.0 25.0) (6.0 5.0 36.0))) > (define y '(1.0 4.0 3.0 6.0 5.0 8.0)) > (define path (elnet-path X y))
> (define X3 '((1.0 1.0) (2.0 1.0) (1.0 2.0) (2.0 2.0) (5.0 1.0) (6.0 1.0) (5.0 2.0) (6.0 2.0) (3.0 5.0) (4.0 5.0) (3.0 6.0) (4.0 6.0))) > (define mpath (multinomial-path X3 '(0 0 0 0 1 1 1 1 2 2 2 2)))
procedure
(plot-coefficient-path model [ #:xvar xvar #:sign-lambda sign-lambda #:label label #:type-coef type-coef #:width width #:height height #:title title #:out-file out-file]) → pict? model : (or/c glmnet-path? glmnet-cv? formula-model?) xvar : (or/c 'lambda 'norm 'dev) = 'lambda sign-lambda : (or/c -1 1) = -1
label : (or/c boolean? design-matrix? (listof (or/c string? symbol?))) = #f type-coef : (or/c 'coef '2norm) = 'coef width : exact-positive-integer? = (plot-width) height : exact-positive-integer? = (plot-height) title : (or/c #f string?) = (plot-title) out-file : (or/c #f image-path/c) = #f
xvar is 'lambda for sign-lambda times log λ, 'norm for the L1 norm of the coefficients, or 'dev for the fraction of deviance explained.
label labels each curve at the end of the path: #f for no labels, #t for the predictor’s name if the model names its predictors, as a formula-model and a fit from named data (see Data arguments) do, and otherwise its position counting from 1, or the names of the predictors, as a list or as the column names of a design matrix. A design matrix without column names gives positions.
type-coef applies to the multinomial and multi-response families: 'coef stacks one plot per class or response, '2norm draws one plot of the 2-norms across them.
width and height are the size of each plot in pixels, and title is its title.
out-file, when given, names a file to which the plot is also written, in the format its extension names (see image-path/c).
An error is raised if every coefficient is zero at every λ, as there is then nothing to plot. A λ of 0 has no position on a log λ axis and is left out: the curves, and their labels, end at the smallest positive λ. If every λ of the path is 0, an error is raised for a log λ axis, as R’s plot stops too; the path can still be plotted against the L1 norm or the deviance ratio.
> (plot-coefficient-path path #:xvar 'norm #:label '("x1" "x2" "x3") #:width 400 #:height 300 #:title "Lasso path")
> (plot-coefficient-path (elnet-path mtcars "mpg" #:predictors '("wt" "hp" "qsec")) #:label #t #:width 400 #:height 300)
> (plot-coefficient-path (elnet-path X y #:lambda '(10.0 5.0))) plot-coefficient-path: every coefficient is zero at every λ,
so there is nothing to plot
λ values: 2
> (plot-coefficient-path (elnet-path X y #:lambda '(0.0))) plot-coefficient-path: every λ of the path is 0, which has
no place on a log λ axis
λ values: '(0.0)
xvar: 'lambda
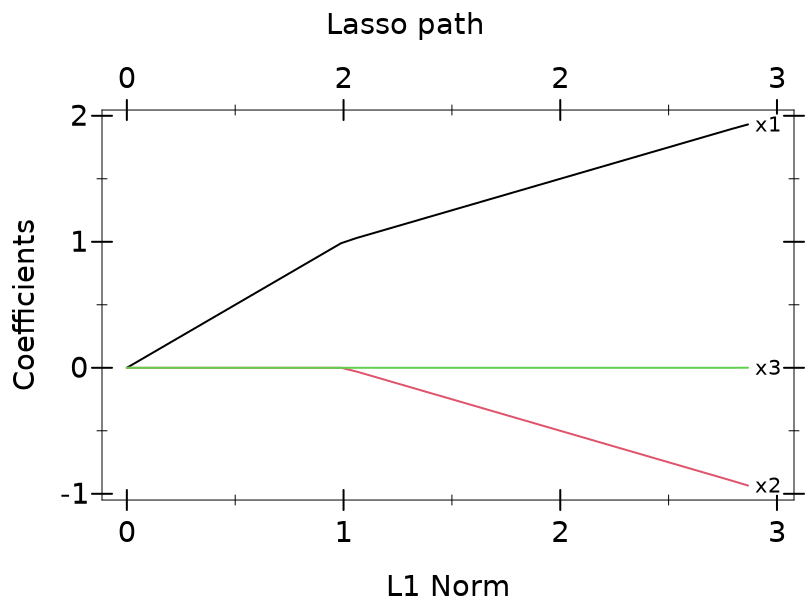
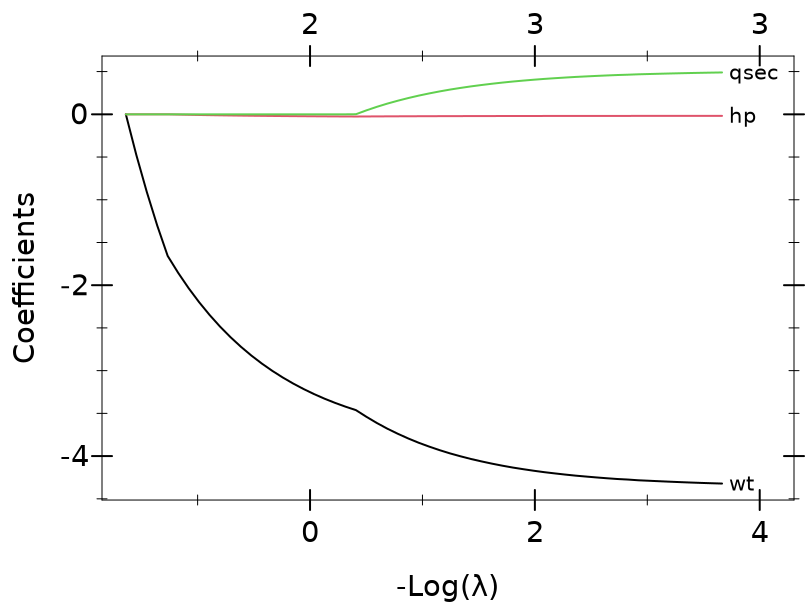
procedure
(coefficient-path-renderers model [ #:xvar xvar #:sign-lambda sign-lambda #:label label #:type-coef type-coef #:response response]) → (listof renderer2d?) model : (or/c glmnet-path? glmnet-cv? formula-model?) xvar : (or/c 'lambda 'norm 'dev) = 'lambda sign-lambda : (or/c -1 1) = -1
label : (or/c boolean? design-matrix? (listof (or/c string? symbol?))) = #f type-coef : (or/c 'coef '2norm) = 'coef response : exact-nonnegative-integer? = 0
The axes are not included. Labels start at the end of the path, where plot-lib cuts them off unless the x axis is widened.
> (length (coefficient-path-renderers path)) 3
> (length (coefficient-path-renderers path #:label #t)) 6
> (length (coefficient-path-renderers mpath #:response 2)) 1
procedure
(plot-cv cv [ #:sign-lambda sign-lambda #:width width #:height height #:title title #:out-file out-file]) → pict? cv : (or/c glmnet-cv? formula-model?) sign-lambda : (or/c -1 1) = -1 width : exact-positive-integer? = (plot-width) height : exact-positive-integer? = (plot-height) title : (or/c #f string?) = (plot-title) out-file : (or/c #f image-path/c) = #f
> (plot-cv cv #:sign-lambda 1 #:width 400 #:height 300)
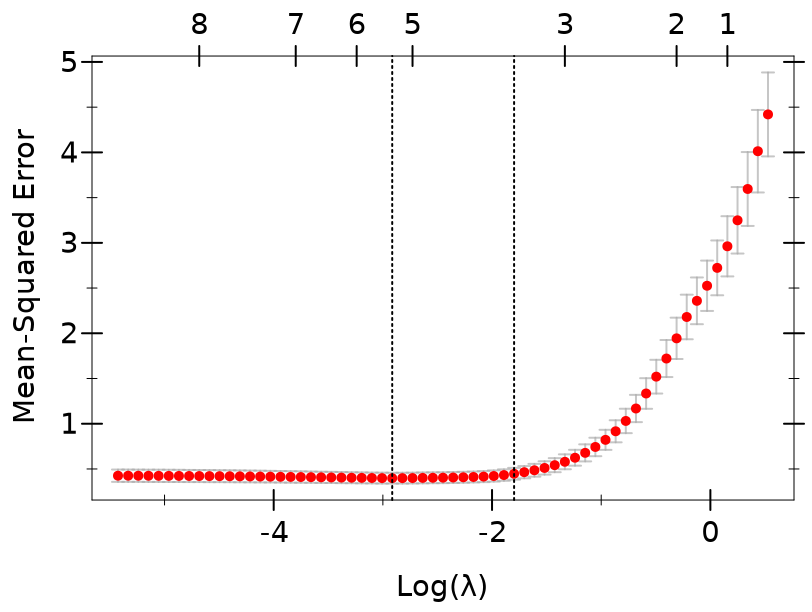
procedure
(cv-renderers cv [#:sign-lambda sign-lambda])
→ (listof renderer2d?) cv : (or/c glmnet-cv? formula-model?) sign-lambda : (or/c -1 1) = -1
> (length (cv-renderers cv)) 4
> (length (cv-renderers cv-model)) 4
value
> (contract-first-order-passes? image-path/c "lasso.PNG") #t
> (contract-first-order-passes? image-path/c "lasso.jpg") #f
> (plot-cv cv #:out-file "cv.jpg") plot-cv: contract violation
expected: (or/c #f image-path/c)
given: "cv.jpg"
in: the #:out-file argument of
(->*
((or/c glmnet-cv? formula-model?))
(#:height
exact-positive-integer?
#:out-file
(or/c #f image-path/c)
#:sign-lambda
(or/c -1 1)
#:title
(or/c #f string?)
#:width
exact-positive-integer?)
pict?)
contract from: <pkgs>/glmnet/plot.rkt
blaming: program
(assuming the contract is correct)
at: <pkgs>/glmnet/plot.rkt:82:3